
C# OCR 影像轉文字教學:無需 Tesseract 即可將影像轉換為文字

想在 C# 中將圖像轉換為文字,而無需進行複雜的 Tesseract 配置嗎? 這篇全面的 IronOCR C# 教學將向您展示如何僅用幾行程式碼在您的 .NET 應用程式中實現強大的光學字元辨識功能。
快速入門:一行程式碼從圖片中擷取文字此範例顯示了瞭解IronOCR的簡單之處 - 只需一行C#代碼即可將您的影像轉換為文本。 它示範如何初始化 OCR 引擎,無需複雜的設定即可立即讀取和檢索文字。
-
1使用 IronOCR 安裝 NuGet Package Manager
-
2複製並運行這段程式碼。
string text = new IronTesseract().Read("image.png").Text;Dim text As String = New IronTesseract().Read("image.png").TextDim text As String = New IronTesseract().Read("image.png").Text -
3部署到您的生產環境進行測試
立即在您的項目中開始使用 IronOCR,並使用 免費試用
最小工作流程(5 個步驟)
- 下載IronOCR - 用於影像到文字轉換的C# OCR程式庫
- 使用
IronTesseract類別可以立即從圖像中讀取文字。 - 對低品質掃描件應用影像濾鏡以提高OCR辨識準確率
- 使用可下載的語言包處理多種語言
- 將結果匯出為可搜尋的PDF文件或提取文字字串
如何在.NET應用程式中讀取圖像中的文字?
要在 .NET 應用程式中實作 C# OCR 影像轉文字功能,您需要一個可靠的 OCR 函式庫。 IronOCR提供了一個使用IronOcr.IronTesseract類的受管理解決方案,在不需要外部依賴的情況下最大化準確性和速度。
首先,將 IronOCR 安裝到您的 Visual Studio 專案中。 您可以直接下載IronOCR DLL或使用NuGet Package Manager。
為什麼選擇IronOCR進行C# OCR而不使用Tesseract?
當您需要在 C# 中將圖像轉換為文字時,IronOCR 比傳統的 Tesseract 實作方式具有顯著優勢:
- 可在純 .NET 環境中立即執行
- 不需要安裝或配置Tesseract
- 運行最新引擎: Tesseract 5 (以及 Tesseract 4 和 3)
- 相容於 .NET Framework 4.6.2 以上、.NET Standard 2 以上,以及 .NET Core 2、3、5、6、7、8、9 和 10
- 與原版Tesseract相比提高了準確性和速度
- 支援 Xamarin、Mono、Azure 和 Docker 部署
- 透過 NuGet 套件管理複雜的 Tesseract 字典
- 自動處理 PDF、多幀 TIFF 和所有主流影像格式
- 校正低品質和傾斜的掃描影像,以獲得最佳結果
如何使用IronOCR C#教程進行基本OCR?
這個 Iron Tesseract C# 範例示範了使用 IronOCR 從圖像中讀取文字的最簡單方法。 IronOcr.IronTesseract類提取文本並以字串形式返回。
// PM> Install-Package IronOcr
using IronOcr;

OcrResult result = new IronTesseract().Read(@"img\Screenshot.png");
Console.WriteLine(result.Text);
// PM> Install-Package IronOcr
using IronOcr;
OcrResult result = new IronTesseract().Read(@"img\Screenshot.png");
Console.WriteLine(result.Text);' PM> Install-Package IronOcr
Imports IronOcr
Private result As OcrResult = (New IronTesseract()).Read("img\Screenshot.png")
Console.WriteLine(result.Text)' PM> Install-Package IronOcr
Imports IronOcr
Private result As OcrResult = (New IronTesseract()).Read("img\Screenshot.png")
Console.WriteLine(result.Text)此代碼從高品質影像中提取出乾淨文字,完全如它所現的樣子:
IronOCR Simple Example

In this simple example we test the accuracy of our C# OCR library to read text from a PNG Image. This is a very basic test, but things will get more complicated as the tutorial continues.

The quick brown fox jumps over the lazy dogIronTesseract類在內部處理複雜的OCR操作。 它自動掃描校準,優化解析度,並使用AI通過IronOCR從影像中讀取文字。
儘管幕後進行了複雜的處理 - 包括圖像分析、引擎優化和智能文字識別 - 但OCR流程仍然高效。
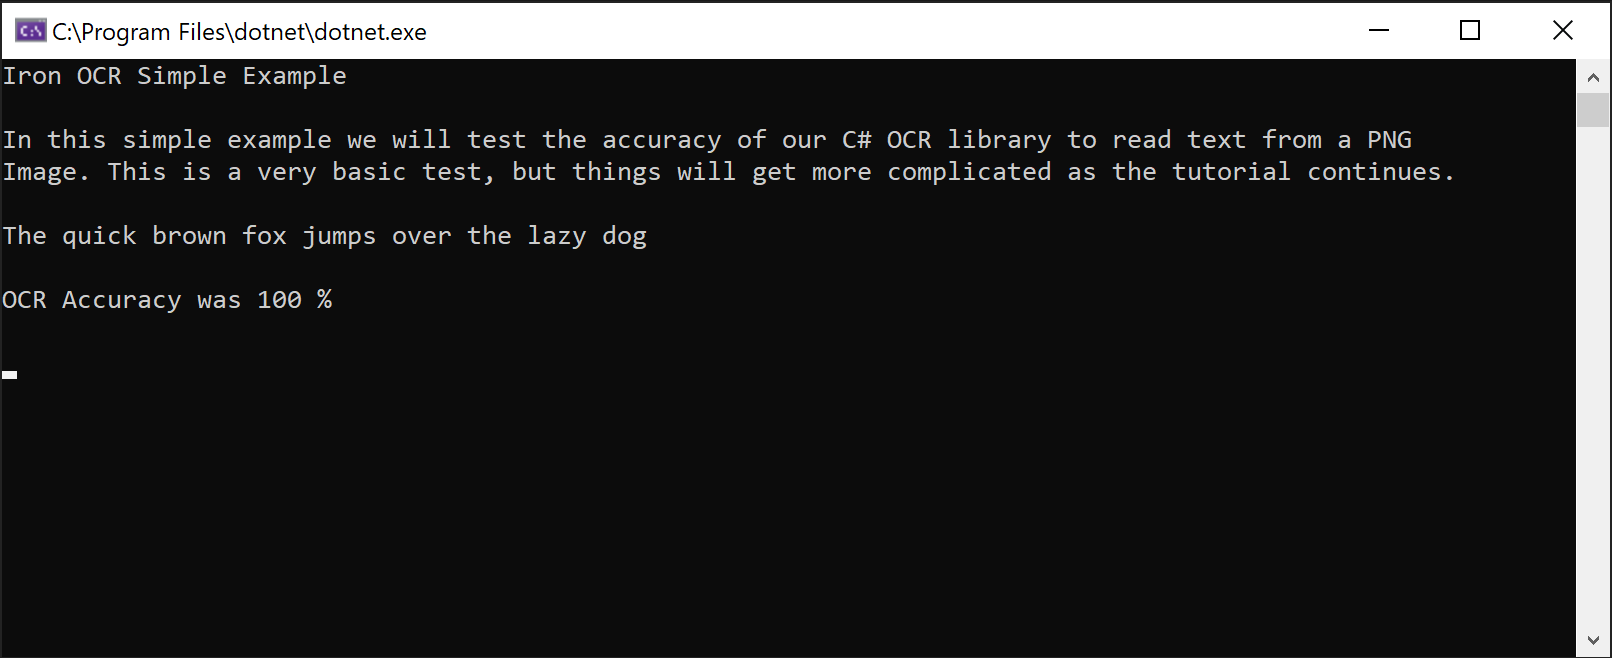 截圖展示IronOCR從PNG影像中提取文本的能力
如何在不需要配置Tesseract的情況下實現高階C# OCR?
對於在C#中將圖像轉換為文字且需要最佳性能的生產應用程序,請同時使用OcrInput和IronTesseract類。 這種方法可以對 OCR 過程進行精細控制。
OcrInput類特性
- 支援多種影像格式:JPEG、TIFF、GIF、BMP、PNG
- 匯入完整的 PDF 檔案或特定頁面
- 自動增強對比度、解析度和影像質量
- 校正旋轉、掃描雜訊、傾斜和負像
IronTesseract類特性
- 支援 127 種以上預先封裝的語言
- 包括 Tesseract 5、4 和 3 引擎
- 文檔類型說明(螢幕截圖、程式碼片段或完整文件)
- 整合條碼讀取功能
- 多種輸出格式:可搜尋的 PDF、HOCR HTML、DOM 物件和字串
如何開始使用OcrInput和IronTesseract?
以下是針對本 IronOCR C# 教學的建議配置,此配置適用於大多數文件類型:
using IronOcr;

IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)這種配置在中等品質的掃描中始終能達到近乎完美的精度。 LoadImageFrames方法能有效處理多頁文件,非常適合批量處理場景。
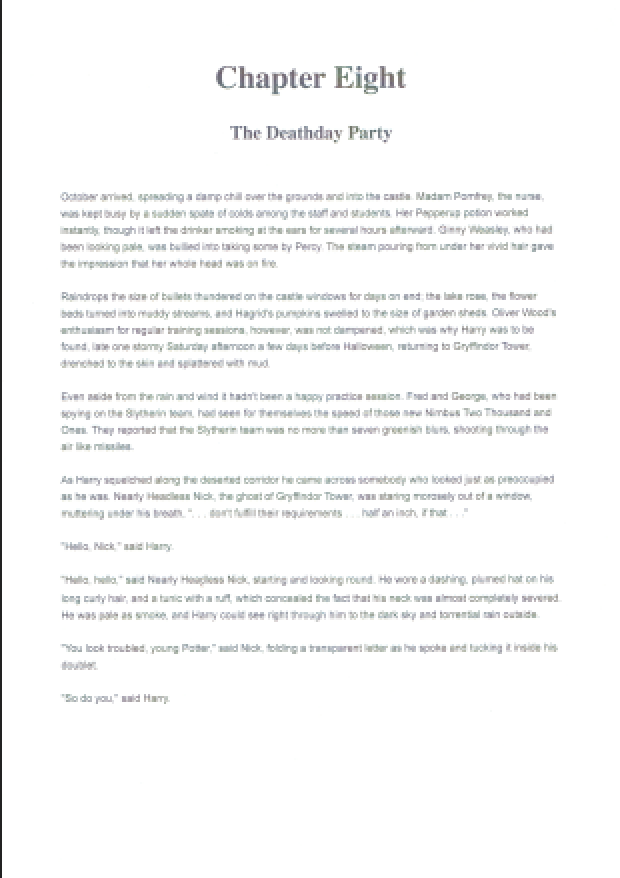
範例 TIFF 文檔,示範 IronOCR 的多頁文字擷取功能
IronOCR 能夠從 TIFF 等掃描文件中的圖像和條碼讀取文字,這充分展現了它如何簡化複雜的 OCR 任務。 該程式庫在處理實際文件方面表現出色,能處理多頁TIFF和PDF文字提取。
IronOCR如何處理低品質掃描件?
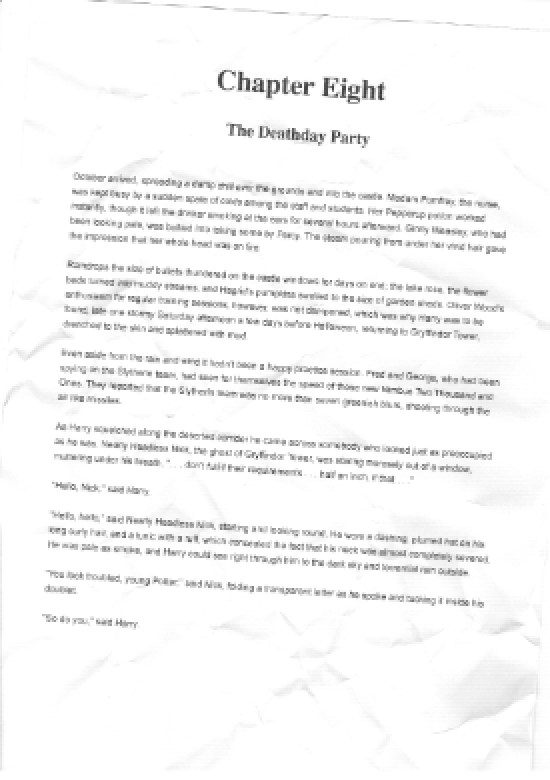
IronOCR 可以使用影像濾波器準確處理具有雜訊的低解析度文件。
在處理包含失真和數位雜訊的不完美掃描時, IronOCR 的效能優於其他 C# OCR 函式庫。 它專為真實場景而設計,而非為完美的測試圖像而設計。
using IronOcr;

IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.LowQuality.tiff", pageindices);
input.Deskew(); // removes rotation and perspective
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.LowQuality.tiff", pageindices);
input.Deskew(); // removes rotation and perspective
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.LowQuality.tiff", pageindices)
input.Deskew() ' removes rotation and perspective
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.LowQuality.tiff", pageindices)
input.Deskew() ' removes rotation and perspective
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)使用Input.Deskew(),即使在低品質掃描中,準確度也顯著提高,幾乎達到高品質結果。 這表明,IronOCR 是 C# OCR 的首選,因為它不會產生 Tesseract 的複雜問題。
影像濾鏡可能會略微增加處理時間,但會顯著縮短整體 OCR 時間。 找到合適的平衡點取決於您的文件品質。
對於大多數情況,Input.Deskew()和Input.DeNoise()能提供可靠的OCR性能改進。 了解更多關於影像預處理技術的資訊。
如何優化OCR效能和速度?
在 C# 中將影像轉換為文字時,影響 OCR 速度的最重要因素是輸入品質。 較高的 DPI(~200 dpi)和最小的噪音可產生最快、最準確的結果。
雖然 IronOCR 在修正不完美文件方面表現出色,但這種增強功能需要額外的處理時間。
選擇壓縮失真最小的影像格式。 由於數位雜訊較低,TIFF 和 PNG 通常比 JPEG 格式的掃描速度更快。
哪些影像濾鏡可以提高OCR速度?
以下濾鏡可顯著提升 C# OCR 影像轉文字工作流程的效能:
OcrInput.Rotate(double degrees): 順時針旋轉圖像(負值為逆時針)OcrInput.Binarize(): 轉換為黑白,在低對比情況下提高效能OcrInput.ToGrayScale(): 轉換為灰階以潛在提高速度OcrInput.Contrast(): 自動調整對比度以提高準確性OcrInput.DeNoise(): 當預期有雜音時去除數位乾擾OcrInput.Invert(): 翻轉顏色以便讀取黑底白字的文本OcrInput.Dilate(): 展開文本邊界OcrInput.Erode(): 縮小文本邊界OcrInput.Deskew(): 校正對齊 - 對於傾斜文件至關重要OcrInput.Despeckle(): 積極的雜訊去除OcrInput.EnhanceResolution: 提高低解析度影像質量OcrInput.DetectPageOrientation(): 檢測並校正頁面旋轉。 傳遞OrientationDetectionMode來控制精準/速度權衡:Fast、Balanced、Detailed或ExtremeDetailed(新增於v2025.8.6)
Scale()和EnhanceResolution()由於v2025.12.3中的已知問題與SaveAsSearchablePdf()不兼容。所有其他篩選器在搜尋型PDF輸出中均能正常工作。如何配置 IronOCR 以獲得最高速度?
使用以下設定可優化處理高品質掃描件的速度:
using IronOcr;

IronTesseract ocr = new IronTesseract();

// Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\\";
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto;
ocr.Language = OcrLanguage.EnglishFast;

using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);

OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
IronTesseract ocr = new IronTesseract();
// Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\\";
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto;
ocr.Language = OcrLanguage.EnglishFast;
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Private ocr As New IronTesseract()
' Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\"
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto
ocr.Language = OcrLanguage.EnglishFast
Using input As New OcrInput()
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End UsingImports IronOcr
Private ocr As New IronTesseract()
' Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\"
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto
ocr.Language = OcrLanguage.EnglishFast
Using input As New OcrInput()
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End Using此優化設置在提高處理速度的同時保持高準確性,與預設設置相比。
如何使用C# OCR讀取特定圖像區域?
下面的Iron Tesseract C#範例顯示了如何使用System.Drawing.Rectangle定位特定區域。 對於文字出現在可預測位置的標準化表格,這種技術非常有價值。
IronOCR能否處理裁切區域以獲得更快的結果?
使用基於像素的座標,您可以將 OCR 限制在特定區域,從而顯著提高速度並防止提取不必要的文字:
using IronOcr;
using IronSoftware.Drawing;

IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
// restrict OCR to a content area for faster processing
Rectangle contentArea = new Rectangle(x: 215, y: 1250, height: 280, width: 1335);
input.LoadImage("img/ComSci.png", contentArea);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
using IronSoftware.Drawing;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
// restrict OCR to a content area for faster processing
Rectangle contentArea = new Rectangle(x: 215, y: 1250, height: 280, width: 1335);
input.LoadImage("img/ComSci.png", contentArea);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Imports IronSoftware.Drawing
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' restrict OCR to a content area for faster processing
Dim contentArea As New Rectangle(x:=215, y:=1250, height:=280, width:=1335)
input.LoadImage("img/ComSci.png", contentArea)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End UsingImports IronOcr
Imports IronSoftware.Drawing
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' restrict OCR to a content area for faster processing
Dim contentArea As New Rectangle(x:=215, y:=1250, height:=280, width:=1335)
input.LoadImage("img/ComSci.png", contentArea)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End Using此定位方法在僅提取相關文本的同時提高了處理速度。 它非常適合結構化文件,例如發票、支票和表單。 相同的裁剪技術也適用於PDF OCR操作。
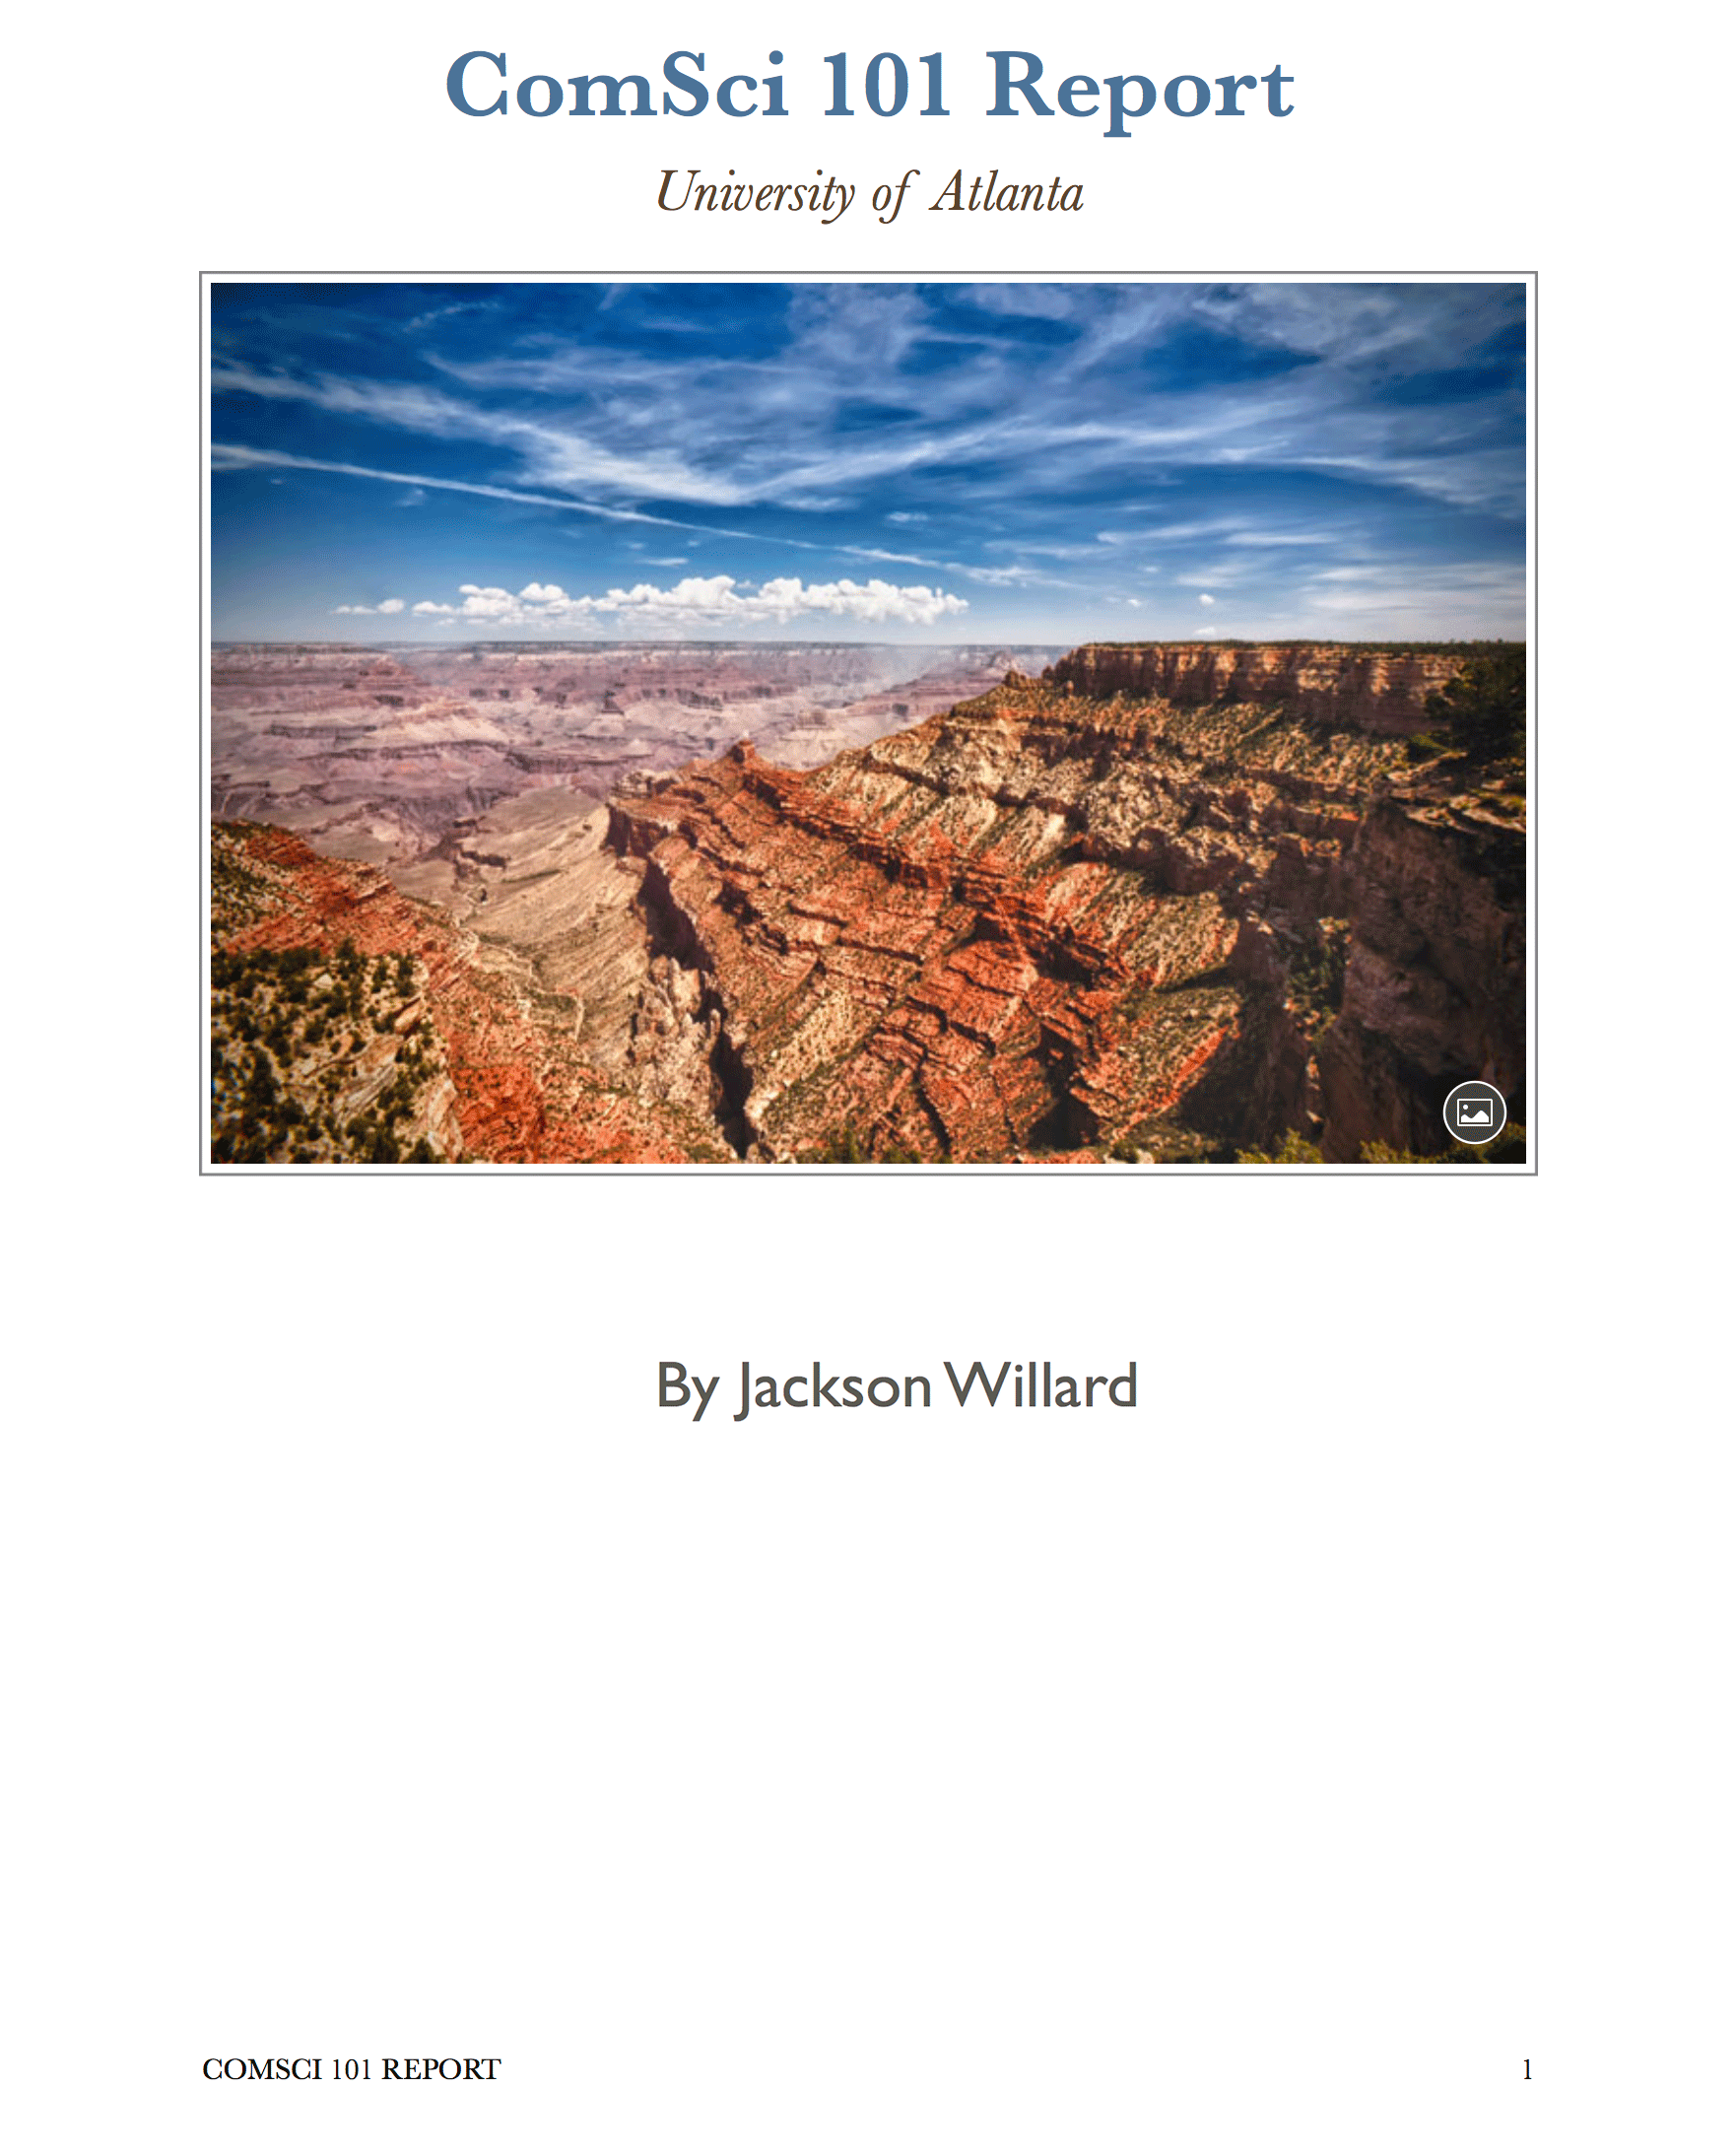 本文檔示範如何使用 IronOCR 的矩形選擇功能進行精確的基於區域的文字擷取。
IronOCR支援多少種語言?
IronOCR 透過便捷的語言套件提供 127 種國際語言。 從我們的網站或透過NuGet Package Manager下載它們為DLL。
透過NuGet介面安裝語言包(搜尋"IronOcr.Languages")或造訪完整的語言包列表。
支援的語言包括阿拉伯語、中文(簡體/繁體)、日語、韓語、印地語、俄語、德語、法語、西班牙語以及其他 115 種語言,每種語言都針對準確的文字辨識進行了最佳化。
如何實現多語言OCR?
本 IronOCR C# 教學範例示範了阿拉伯文字辨識:
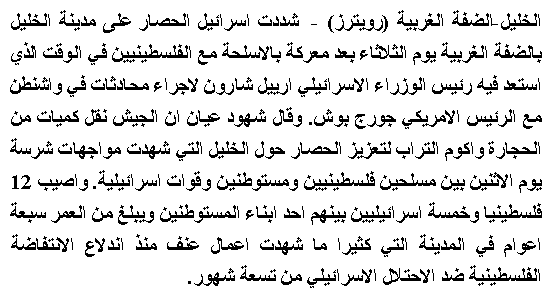
IronOCR能夠從GIF圖像中準確提取阿拉伯語文字
// PM> Install IronOcr.Languages.Arabic
using IronOcr;

IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.Arabic;

using OcrInput input = new OcrInput();
input.LoadImageFrame("img/arabic.gif", 1);
// add image filters if needed
// In this case, even thought input is very low quality
// IronTesseract can read what conventional Tesseract cannot.

OcrResult result = ocr.Read(input);

// Console can't print Arabic on Windows easily.
// Let's save to disk instead.
result.SaveAsTextFile("arabic.txt");
// PM> Install IronOcr.Languages.Arabic
using IronOcr;
IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.Arabic;
using OcrInput input = new OcrInput();
input.LoadImageFrame("img/arabic.gif", 1);
// add image filters if needed
// In this case, even thought input is very low quality
// IronTesseract can read what conventional Tesseract cannot.
OcrResult result = ocr.Read(input);
// Console can't print Arabic on Windows easily.
// Let's save to disk instead.
result.SaveAsTextFile("arabic.txt");' PM> Install IronOcr.Languages.Arabic
Imports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.Arabic
Using input As New OcrInput()
input.LoadImageFrame("img/arabic.gif", 1)
' add image filters if needed
' In this case, even thought input is very low quality
' IronTesseract can read what conventional Tesseract cannot.
Dim result As OcrResult = ocr.Read(input)
' Console can't print Arabic on Windows easily.
' Let's save to disk instead.
result.SaveAsTextFile("arabic.txt")
End Using' PM> Install IronOcr.Languages.Arabic
Imports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.Arabic
Using input As New OcrInput()
input.LoadImageFrame("img/arabic.gif", 1)
' add image filters if needed
' In this case, even thought input is very low quality
' IronTesseract can read what conventional Tesseract cannot.
Dim result As OcrResult = ocr.Read(input)
' Console can't print Arabic on Windows easily.
' Let's save to disk instead.
result.SaveAsTextFile("arabic.txt")
End UsingIronOCR 能處理多語言文件嗎?
當文件包含多種語言時,請設定 IronOCR 以支援多語言:
using IronOcr;

IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.ChineseSimplified;

// We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English);
// Optionally add custom tesseract .traineddata files by specifying a file path

using OcrInput input = new OcrInput();
input.LoadImage("img/MultiLanguage.jpeg");
OcrResult result = ocr.Read(input);
result.SaveAsTextFile("MultiLanguage.txt");
using IronOcr;
IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.ChineseSimplified;
// We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English);
// Optionally add custom tesseract .traineddata files by specifying a file path
using OcrInput input = new OcrInput();
input.LoadImage("img/MultiLanguage.jpeg");
OcrResult result = ocr.Read(input);
result.SaveAsTextFile("MultiLanguage.txt");Imports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.ChineseSimplified
' We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English)
' Optionally add custom tesseract .traineddata files by specifying a file path
Using input As New OcrInput()
input.LoadImage("img/MultiLanguage.jpeg")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsTextFile("MultiLanguage.txt")
End UsingImports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.ChineseSimplified
' We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English)
' Optionally add custom tesseract .traineddata files by specifying a file path
Using input As New OcrInput()
input.LoadImage("img/MultiLanguage.jpeg")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsTextFile("MultiLanguage.txt")
End Using如何使用C# OCR處理多頁文件?
IronOCR將多頁或多影像合併為一個單一的OcrResult。 此功能允許強大的能力,如創建可搜索的PDF和從整個文件集提取文本。
在一次 OCR 操作中混合搭配各種來源—影像、TIFF 幀和 PDF 頁面:
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);

OcrResult result = ocr.Read(input);

Console.WriteLine($"{result.Pages.Length} Pages"); // 3 Pages
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine($"{result.Pages.Length} Pages"); // 3 PagesImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine($"{result.Pages.Length} Pages") ' 3 PagesImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine($"{result.Pages.Length} Pages") ' 3 Pages高效處理TIFF檔案的所有頁面:
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("MultiFrame.Tiff", pageindices);
OcrResult result = ocr.Read(input);

Console.WriteLine(result.Text);
Console.WriteLine($"{result.Pages.Length} Pages");
// 1 page for every frame (page) in the TIFF
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("MultiFrame.Tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
Console.WriteLine($"{result.Pages.Length} Pages");
// 1 page for every frame (page) in the TIFFImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("MultiFrame.Tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
Console.WriteLine($"{result.Pages.Length} Pages")
' 1 page for every frame (page) in the TIFFImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("MultiFrame.Tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
Console.WriteLine($"{result.Pages.Length} Pages")
' 1 page for every frame (page) in the TIFF將TIFF或PDF檔案轉換為可搜尋格式:
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
input.Title = "Quarterly Report";
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);

OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
input.Title = "Quarterly Report";
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Quarterly Report"
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Quarterly Report"
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")將現有PDF文件轉換為可搜尋版本:
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
input.Title = "Pdf Metadata Name";
input.LoadPdf("example.pdf", Password: "password");
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
input.Title = "Pdf Metadata Name";
input.LoadPdf("example.pdf", Password: "password");
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Pdf Metadata Name"
input.LoadPdf("example.pdf", Password:= "password")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Pdf Metadata Name"
input.LoadPdf("example.pdf", Password:= "password")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")對 TIFF 格式轉換也應用相同的技術:
using IronOcr;

var ocr = new IronTesseract();

using (var input = new OcrInput())
{
    // Configure document properties
    input.Title = "Scanned Archive Document";

    // Select pages to process
    var pageIndices = new int[] { 1, 2 };
    input.LoadImageFrames("example.tiff", pageIndices);

    // Create searchable PDF from TIFF
    OcrResult result = ocr.Read(input);
    result.SaveAsSearchablePdf("searchable.pdf");
}
using IronOcr;
var ocr = new IronTesseract();
using (var input = new OcrInput())
{
// Configure document properties
input.Title = "Scanned Archive Document";
// Select pages to process
var pageIndices = new int[] { 1, 2 };
input.LoadImageFrames("example.tiff", pageIndices);
// Create searchable PDF from TIFF
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");
}Imports IronOcr
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' Configure document properties
input.Title = "Scanned Archive Document"
' Select pages to process
Dim pageIndices As Integer() = {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Create searchable PDF from TIFF
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")
End UsingImports IronOcr
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' Configure document properties
input.Title = "Scanned Archive Document"
' Select pages to process
Dim pageIndices As Integer() = {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Create searchable PDF from TIFF
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")
End Using如何將 OCR 結果匯出為 HOCR HTML?
IronOCR 支援 HOCR HTML 匯出,可在保留佈局資訊的同時,實現結構化PDF 到 HTML和TIFF 到 HTML 的轉換:
using IronOcr;

var ocr = new IronTesseract();

using (var input = new OcrInput())
{
    // Set HTML title
    input.Title = "Document Archive";

    // Process multiple document types
    input.LoadImage("image2.jpeg");
    input.LoadPdf("example.pdf", Password: "password");

    // Add TIFF pages
    var pageIndices = new int[] { 1, 2 };
    input.LoadImageFrames("example.tiff", pageIndices);

    // Export as HOCR with position data
    OcrResult result = ocr.Read(input);
    result.SaveAsHocrFile("hocr.html");
}
using IronOcr;
var ocr = new IronTesseract();
using (var input = new OcrInput())
{
// Set HTML title
input.Title = "Document Archive";
// Process multiple document types
input.LoadImage("image2.jpeg");
input.LoadPdf("example.pdf", Password: "password");
// Add TIFF pages
var pageIndices = new int[] { 1, 2 };
input.LoadImageFrames("example.tiff", pageIndices);
// Export as HOCR with position data
OcrResult result = ocr.Read(input);
result.SaveAsHocrFile("hocr.html");
}Imports IronOcr
Dim ocr = New IronTesseract()
Using input = New OcrInput()
' Set HTML title
input.Title = "Document Archive"
' Process multiple document types
input.LoadImage("image2.jpeg")
input.LoadPdf("example.pdf", Password:="password")
' Add TIFF pages
Dim pageIndices = New Integer() {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Export as HOCR with position data
Dim result As OcrResult = ocr.Read(input)
result.SaveAsHocrFile("hocr.html")
End UsingImports IronOcr
Dim ocr = New IronTesseract()
Using input = New OcrInput()
' Set HTML title
input.Title = "Document Archive"
' Process multiple document types
input.LoadImage("image2.jpeg")
input.LoadPdf("example.pdf", Password:="password")
' Add TIFF pages
Dim pageIndices = New Integer() {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Export as HOCR with position data
Dim result As OcrResult = ocr.Read(input)
result.SaveAsHocrFile("hocr.html")
End UsingIronOCR 能同時讀取條碼和文字嗎?
IronOCR獨特地結合了文本識別和條碼讀取功能,消除了對於單獨庫的需求:
// Enable combined text and barcode recognition
using IronOcr;

var ocr = new IronTesseract();

// Enable barcode detection
ocr.Configuration.ReadBarCodes = true;

using (var input = new OcrInput())
{
    // Load image containing both text and barcodes
    input.LoadImage("img/Barcode.png");

    // Process both text and barcodes
    var result = ocr.Read(input);

    // Extract barcode data
    foreach (var barcode in result.Barcodes)
    {
        Console.WriteLine($"Barcode Value: {barcode.Value}");
        Console.WriteLine($"Format: {barcode.Format}");
    }
}
// Enable combined text and barcode recognition
using IronOcr;
var ocr = new IronTesseract();
// Enable barcode detection
ocr.Configuration.ReadBarCodes = true;
using (var input = new OcrInput())
{
// Load image containing both text and barcodes
input.LoadImage("img/Barcode.png");
// Process both text and barcodes
var result = ocr.Read(input);
// Extract barcode data
foreach (var barcode in result.Barcodes)
{
Console.WriteLine($"Barcode Value: {barcode.Value}");
Console.WriteLine($"Format: {barcode.Format}");
}
}' Enable combined text and barcode recognition
Imports IronOcr
Dim ocr = New IronTesseract()
' Enable barcode detection
ocr.Configuration.ReadBarCodes = True
Using input = New OcrInput()
' Load image containing both text and barcodes
input.LoadImage("img/Barcode.png")
' Process both text and barcodes
Dim result = ocr.Read(input)
' Extract barcode data
For Each barcode In result.Barcodes
Console.WriteLine($"Barcode Value: {barcode.Value}")
Console.WriteLine($"Format: {barcode.Format}")
Next
End Using' Enable combined text and barcode recognition
Imports IronOcr
Dim ocr = New IronTesseract()
' Enable barcode detection
ocr.Configuration.ReadBarCodes = True
Using input = New OcrInput()
' Load image containing both text and barcodes
input.LoadImage("img/Barcode.png")
' Process both text and barcodes
Dim result = ocr.Read(input)
' Extract barcode data
For Each barcode In result.Barcodes
Console.WriteLine($"Barcode Value: {barcode.Value}")
Console.WriteLine($"Format: {barcode.Format}")
Next
End Using如何取得詳細的OCR結果和元資料?
IronOCR 結果物件提供全面的資料,高級開發人員可以利用這些資料開發複雜的應用程式。
每個OcrResult包含分層集合:頁面、段落、行、單詞和字元。 所有元素均包含詳細的元資料,例如位置、字體資訊和置信度評分。
可以將單一元素(段落、單字、條碼)匯出為圖像或點陣圖以進行進一步處理:
using System;
using IronOcr;
using IronSoftware.Drawing;

// Configure with barcode support
IronTesseract ocr = new IronTesseract
{
    Configuration = { ReadBarCodes = true }
};

using OcrInput input = new OcrInput();

// Process multi-page document
int[] pageIndices = { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageIndices);

OcrResult result = ocr.Read(input);

// Navigate the complete results hierarchy
foreach (var page in result.Pages)
{
    // Page-level data
    int pageNumber = page.PageNumber;
    string pageText = page.Text;
    int pageWordCount = page.WordCount;

    // Extract page elements
    OcrResult.Barcode[] barcodes = page.Barcodes;
    AnyBitmap pageImage = page.ToBitmap(input);
    double pageWidth = page.Width;
    double pageHeight = page.Height;

    foreach (var paragraph in page.Paragraphs)
    {
        // Paragraph properties
        int paragraphNumber = paragraph.ParagraphNumber;
        string paragraphText = paragraph.Text;
        double paragraphConfidence = paragraph.Confidence;
        var textDirection = paragraph.TextDirection;

        foreach (var line in paragraph.Lines)
        {
            // Line details including baseline information
            string lineText = line.Text;
            double lineConfidence = line.Confidence;
            double baselineAngle = line.BaselineAngle;
            double baselineOffset = line.BaselineOffset;

            foreach (var word in line.Words)
            {
                // Word-level data
                string wordText = word.Text;
                double wordConfidence = word.Confidence;

                // Font information (when available)
                if (word.Font != null)
                {
                    string fontName = word.Font.FontName;
                    double fontSize = word.Font.FontSize;
                    bool isBold = word.Font.IsBold;
                    bool isItalic = word.Font.IsItalic;
                }

                foreach (var character in word.Characters)
                {
                    // Character-level analysis
                    string charText = character.Text;
                    double charConfidence = character.Confidence;

                    // Alternative character choices for spell-checking
                    OcrResult.Choice[] alternatives = character.Choices;
                }
            }
        }
    }
}
using System;
using IronOcr;
using IronSoftware.Drawing;
// Configure with barcode support
IronTesseract ocr = new IronTesseract
{
Configuration = { ReadBarCodes = true }
};
using OcrInput input = new OcrInput();
// Process multi-page document
int[] pageIndices = { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageIndices);
OcrResult result = ocr.Read(input);
// Navigate the complete results hierarchy
foreach (var page in result.Pages)
{
// Page-level data
int pageNumber = page.PageNumber;
string pageText = page.Text;
int pageWordCount = page.WordCount;
// Extract page elements
OcrResult.Barcode[] barcodes = page.Barcodes;
AnyBitmap pageImage = page.ToBitmap(input);
double pageWidth = page.Width;
double pageHeight = page.Height;
foreach (var paragraph in page.Paragraphs)
{
// Paragraph properties
int paragraphNumber = paragraph.ParagraphNumber;
string paragraphText = paragraph.Text;
double paragraphConfidence = paragraph.Confidence;
var textDirection = paragraph.TextDirection;
foreach (var line in paragraph.Lines)
{
// Line details including baseline information
string lineText = line.Text;
double lineConfidence = line.Confidence;
double baselineAngle = line.BaselineAngle;
double baselineOffset = line.BaselineOffset;
foreach (var word in line.Words)
{
// Word-level data
string wordText = word.Text;
double wordConfidence = word.Confidence;
// Font information (when available)
if (word.Font != null)
{
string fontName = word.Font.FontName;
double fontSize = word.Font.FontSize;
bool isBold = word.Font.IsBold;
bool isItalic = word.Font.IsItalic;
}
foreach (var character in word.Characters)
{
// Character-level analysis
string charText = character.Text;
double charConfidence = character.Confidence;
// Alternative character choices for spell-checking
OcrResult.Choice[] alternatives = character.Choices;
}
}
}
}
}Imports System
Imports IronOcr
Imports IronSoftware.Drawing
' Configure with barcode support
Dim ocr As New IronTesseract With {
.Configuration = New OcrConfiguration With {
.ReadBarCodes = True
}
}
Using input As New OcrInput()
' Process multi-page document
Dim pageIndices() As Integer = {1, 2}
input.LoadImageFrames("img\Potter.tiff", pageIndices)
Dim result As OcrResult = ocr.Read(input)
' Navigate the complete results hierarchy
For Each page In result.Pages
' Page-level data
Dim pageNumber As Integer = page.PageNumber
Dim pageText As String = page.Text
Dim pageWordCount As Integer = page.WordCount
' Extract page elements
Dim barcodes() As OcrResult.Barcode = page.Barcodes
Dim pageImage As AnyBitmap = page.ToBitmap(input)
Dim pageWidth As Double = page.Width
Dim pageHeight As Double = page.Height
For Each paragraph In page.Paragraphs
' Paragraph properties
Dim paragraphNumber As Integer = paragraph.ParagraphNumber
Dim paragraphText As String = paragraph.Text
Dim paragraphConfidence As Double = paragraph.Confidence
Dim textDirection = paragraph.TextDirection
For Each line In paragraph.Lines
' Line details including baseline information
Dim lineText As String = line.Text
Dim lineConfidence As Double = line.Confidence
Dim baselineAngle As Double = line.BaselineAngle
Dim baselineOffset As Double = line.BaselineOffset
For Each word In line.Words
' Word-level data
Dim wordText As String = word.Text
Dim wordConfidence As Double = word.Confidence
' Font information (when available)
If word.Font IsNot Nothing Then
Dim fontName As String = word.Font.FontName
Dim fontSize As Double = word.Font.FontSize
Dim isBold As Boolean = word.Font.IsBold
Dim isItalic As Boolean = word.Font.IsItalic
End If
For Each character In word.Characters
' Character-level analysis
Dim charText As String = character.Text
Dim charConfidence As Double = character.Confidence
' Alternative character choices for spell-checking
Dim alternatives() As OcrResult.Choice = character.Choices
Next
Next
Next
Next
Next
End UsingImports System
Imports IronOcr
Imports IronSoftware.Drawing
' Configure with barcode support
Dim ocr As New IronTesseract With {
.Configuration = New OcrConfiguration With {
.ReadBarCodes = True
}
}
Using input As New OcrInput()
' Process multi-page document
Dim pageIndices() As Integer = {1, 2}
input.LoadImageFrames("img\Potter.tiff", pageIndices)
Dim result As OcrResult = ocr.Read(input)
' Navigate the complete results hierarchy
For Each page In result.Pages
' Page-level data
Dim pageNumber As Integer = page.PageNumber
Dim pageText As String = page.Text
Dim pageWordCount As Integer = page.WordCount
' Extract page elements
Dim barcodes() As OcrResult.Barcode = page.Barcodes
Dim pageImage As AnyBitmap = page.ToBitmap(input)
Dim pageWidth As Double = page.Width
Dim pageHeight As Double = page.Height
For Each paragraph In page.Paragraphs
' Paragraph properties
Dim paragraphNumber As Integer = paragraph.ParagraphNumber
Dim paragraphText As String = paragraph.Text
Dim paragraphConfidence As Double = paragraph.Confidence
Dim textDirection = paragraph.TextDirection
For Each line In paragraph.Lines
' Line details including baseline information
Dim lineText As String = line.Text
Dim lineConfidence As Double = line.Confidence
Dim baselineAngle As Double = line.BaselineAngle
Dim baselineOffset As Double = line.BaselineOffset
For Each word In line.Words
' Word-level data
Dim wordText As String = word.Text
Dim wordConfidence As Double = word.Confidence
' Font information (when available)
If word.Font IsNot Nothing Then
Dim fontName As String = word.Font.FontName
Dim fontSize As Double = word.Font.FontSize
Dim isBold As Boolean = word.Font.IsBold
Dim isItalic As Boolean = word.Font.IsItalic
End If
For Each character In word.Characters
' Character-level analysis
Dim charText As String = character.Text
Dim charConfidence As Double = character.Confidence
' Alternative character choices for spell-checking
Dim alternatives() As OcrResult.Choice = character.Choices
Next
Next
Next
Next
Next
End Using總結
IronOCR為C#開發者提供了最先進的Tesseract API實現,可在Windows、Linux和Mac平台上運行。 IronOCR 能夠準確地從圖像中讀取文字——即使是從不完美的文件中讀取——這使其區別於基本的 OCR 解決方案。
該程式庫的獨特功能包括整合條碼讀取功能,以及將結果匯出為可搜尋的 PDF 或 HOCR HTML 的功能,這些功能在標準的 Tesseract 實作中是不可用的。
展望未來
要繼續精通 IronOCR:
原始碼下載
準備好在您的應用程式中實現 C# OCR 圖像到文字的轉換功能了嗎? 下載IronOCR並立即開始您的免費試用。
常見問題
什麼是IronOCR,與Tesseract有什麼不同?
IronOCR是一個C# OCR程式庫,提供影像轉文字的功能,而不需要像Tesseract那樣複雜的安裝和配置。它包含Tesseract引擎,但針對.NET應用程式進行優化。
如何使用C# IronOCR從影像中擷取文字?
要使用IronOCR從影像中擷取文字,可以使用IronTesseract類別。對於簡單的使用案例,初始化一個新實例並呼叫Read方法,傳入影像檔案路徑,即可返回識別的文字。
IronOCR支持哪些影像檔案格式?
IronOCR支持多種影像格式,包括JPEG、TIFF、GIF、BMP和PNG。它還可以處理整個PDF或其中的特定頁面。
影像過濾器如何增強IronOCR的OCR準確性?
IronOCR中的影像過濾器可以通過校正影像缺陷,如傾斜、噪聲和對比度差,來增強OCR準確性。Deskew、DeNoise和EnhanceResolution等過濾器常被使用以改善輸入品質。
IronOCR 能夠處理多種語言嗎?
是的,IronOCR支持127種國際語言。您可以輕鬆配置它以識別不同語言的文字,方法是從NuGet或Iron Software的網站下載語言包。
IronOCR如何用於特定區域文字擷取?
IronOCR可以使用System.Drawing.Rectangle來鎖定特定區域進行文字擷取,這樣可以限制OCR操作於定義的區域,提高速度並防止不需要的文字擷取。
使用IronOCR進行多頁文件處理的好處是什麼?
IronOCR可以在單次OCR操作中處理多個頁面或影像,產生的結果可以合併成可搜尋的PDF或完整的文字檔。
IronOCR是否支持匯出OCR結果為HTML?
是的,IronOCR允許您以HOCR HTML形式匯出OCR結果,保存佈局信息,並允許將PDF和TIFF有結構地轉換為HTML。
IronOCR可以同時讀取條碼和文字嗎?
IronOCR除了執行文字識別外,還可以讀取條碼,將兩種功能結合在一個程式庫中,這樣不需另行使用條碼識別軟體。
如何優化IronOCR來加快OCR處理速度?
為了優化IronOCR的速度,使用高品質且噪音最小的影像,利用合適的影像過濾器,並配置如BlackListCharacters和PageSegmentationMode等設置來進行優化處理。

Jacob Mellor是Iron Software的首席技術官,也是開創C# PDF技術的前瞻性工程師。作為Iron Software核心代碼庫的原始開發者,他自公司成立以來就塑造了公司的產品架構,並與CEO Cameron Rimington將公司轉型為服務NASA、Tesla以及全球政府機構的50多人公司。

