
C# OCR 画像からテキストへのチュートリアル: Tesseractを使わずに画像をテキストに変換する

複雑な Tesseract 構成の手間をかけずに、C# で画像をテキストに変換したいとお考えですか? この包括的な IronOCR C# チュートリアルでは、わずか数行のコードで .NET アプリケーションに強力な光学式文字認識を実装する方法を説明します。
クイックスタート:1行で画像からテキストを抽出するこの例では、IronOCRを簡単に理解する方法を示しています。たった1行のC#コードで画像をテキストに変換できます。 OCR エンジンを初期化し、複雑な設定なしですぐにテキストを読み取って取得する方法を示します。
-
1IronOCR を NuGet Package Manager でインストールします
-
2このコード スニペットをコピーして実行します。
string text = new IronTesseract().Read("image.png").Text;Dim text As String = New IronTesseract().Read("image.png").TextDim text As String = New IronTesseract().Read("image.png").Text -
3実際の環境でテストするためにデプロイする
今日からご自身のプロジェクトでIronOCRを使い始めるには、無料トライアルをお試しください。
最小限のワークフロー(5ステップ)
- IronOCRをダウンロード - 画像をテキストに変換するC# OCRライブラリ
IronTesseractクラスを使用して画像からテキストを即座に読み取ります- 画像フィルターを適用して、低品質のスキャンの OCR 精度を高めます
- ダウンロード可能な言語パックを使用して複数の言語を処理
- 結果を検索可能なPDFとしてエクスポートするか、テキスト文字列を抽出します
.NET アプリケーションで画像からテキストを読み取るにはどうすればよいでしょうか?
.NET アプリケーションで C# OCR 画像からテキストへの機能を実現するには、信頼性の高い OCR ライブラリが必要です。 IronOCRは、外部依存性を必要とせずに、正確さと速度を最大化するIronOcr.IronTesseractクラスを使用する管理されたソリューションを提供します。
まず、Visual Studio プロジェクトに IronOCR をインストールします。 IronOCR DLLを直接ダウンロードするか、NuGetパッケージマネージャーを使用してください。
なぜC# OCRにTesseractを使わずにIronOCRを選ぶべきか?
C# で画像をテキストに変換する必要がある場合、IronOCR は従来の Tesseract 実装に比べて大きな利点を提供します。
- 純粋な.NET環境ですぐに動作します
- Tesseractのインストールや設定は不要
- 最新のエンジンを実行: Tesseract 5 (および Tesseract 4 と 3)
- .NET Framework 4.6.2 以降、.NET Standard 2 以降、および .NET Core 2、3、5、6、7、8、9、10 に対応
- バニラのTesseractと比較して精度と速度が向上します
- Xamarin、Mono、Azure、Docker のデプロイメントをサポート
- NuGet パッケージを通じて複雑な Tesseract 辞書を管理します
- PDF、マルチフレームTIFF、およびすべての主要な画像形式を自動的に処理します
- 低品質や歪んだスキャンを補正して最適な結果を実現します
基本的なOCRのためのIronOCR C#チュートリアルを使用する方法?
この Iron Tesseract C# の例では、IronOCR を使用して画像からテキストを読み取る最も簡単な方法を示します。 IronOcr.IronTesseractクラスはテキストを抽出し、それを文字列として返します。
// PM> Install-Package IronOcr
using IronOcr;

OcrResult result = new IronTesseract().Read(@"img\Screenshot.png");
Console.WriteLine(result.Text);
// PM> Install-Package IronOcr
using IronOcr;
OcrResult result = new IronTesseract().Read(@"img\Screenshot.png");
Console.WriteLine(result.Text);' PM> Install-Package IronOcr
Imports IronOcr
Private result As OcrResult = (New IronTesseract()).Read("img\Screenshot.png")
Console.WriteLine(result.Text)' PM> Install-Package IronOcr
Imports IronOcr
Private result As OcrResult = (New IronTesseract()).Read("img\Screenshot.png")
Console.WriteLine(result.Text)このコードは高品質な画像から清潔なテキストを抽出し、正確に表示されます。
IronOCR Simple Example

In this simple example we test the accuracy of our C# OCR library to read text from a PNG Image. This is a very basic test, but things will get more complicated as the tutorial continues.

The quick brown fox jumps over the lazy dogIronTesseractクラスは複雑なOCR操作を内部で処理します。 これは、自動で整列をスキャンし、解像度を最適化し、AIを使用してIronOCRを使って画像からテキストを読み取ります。
画像分析、エンジンの最適化、インテリジェントなテキスト認識を含む複雑な処理が舞台裏で行われているにもかかわらず、OCRプロセスは効率的なままです。
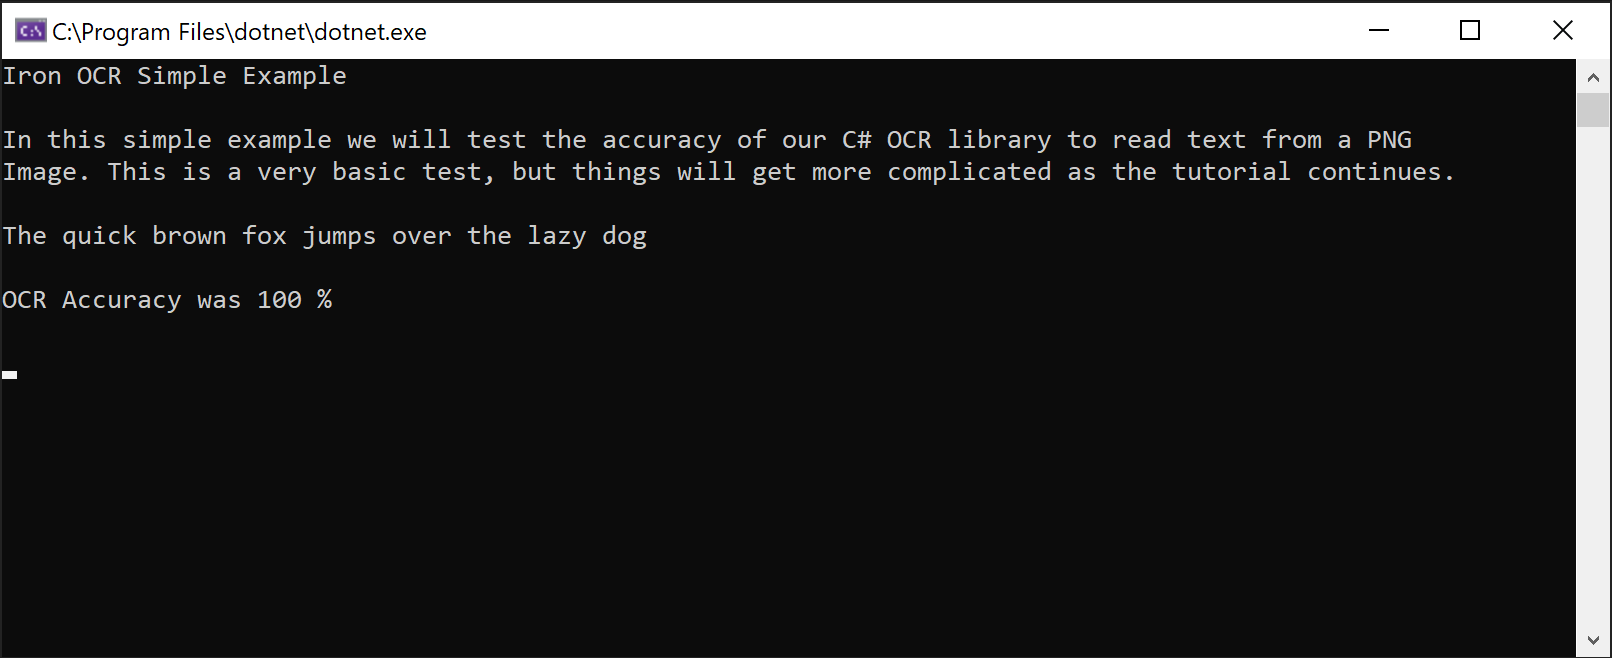 IronOCRがPNG画像からテキストを抽出する能力を示すスクリーンショット
Tesseractの設定なしで高度なC# OCRを実装する方法?
C#で画像をテキストに変換する際に最適なパフォーマンスを求めるプロダクションアプリケーションには、OcrInput クラスと IronTesseract クラスを一緒に使用してください。 このアプローチにより、OCR プロセスをきめ細かく制御できます。
OcrInput クラスの特徴
- 複数の画像形式を処理: JPEG、TIFF、GIF、BMP、PNG
- PDF全体または特定のページをインポートします
- コントラスト、解像度、画質を自動的に向上します
- 回転、スキャンノイズ、傾き、ネガティブイメージを修正します
IronTesseract クラスの特徴
- 127以上のプリパッケージされた言語へのアクセス
- Tesseract 5、4、3エンジン搭載
- ドキュメントタイプの指定(スクリーンショット、スニペット、または完全なドキュメント)
- 統合バーコード読み取り機能
- 複数の出力形式: 検索可能なPDF、HOCR HTML、DOMオブジェクト、文字列
OcrInput と IronTesseract を使用して始めるには?
ほとんどのドキュメント タイプで適切に機能する、この IronOCR C# チュートリアルの推奨構成は次のとおりです。
using IronOcr;

IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)この構成では、中品質のスキャンでほぼ完璧な精度が一貫して達成されます。 LoadImageFramesメソッドは多ページのドキュメントを効率的に処理し、バッチ処理シナリオに理想的です。
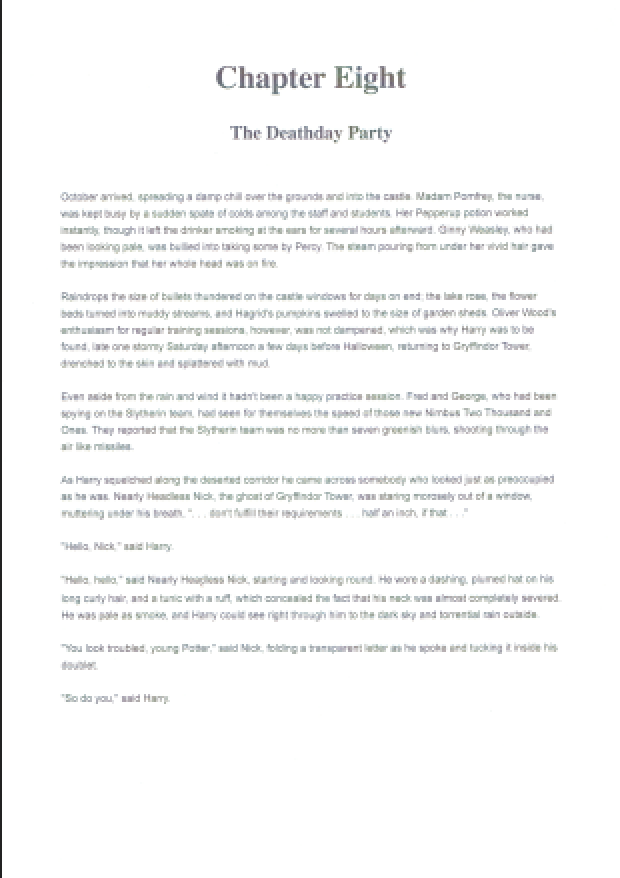
IronOCR の複数ページテキスト抽出機能を示すサンプル TIFF ドキュメント
TIFF などのスキャンされたドキュメント内の画像やバーコードからテキストを読み取る機能は、IronOCR が複雑な OCR タスクをいかに簡素化するかを示しています。 このライブラリは、実世界のドキュメントで優れており、多ページのTIFFやPDFテキスト抽出を処理します。
IronOCR は低品質のスキャンをどのように処理しますか?
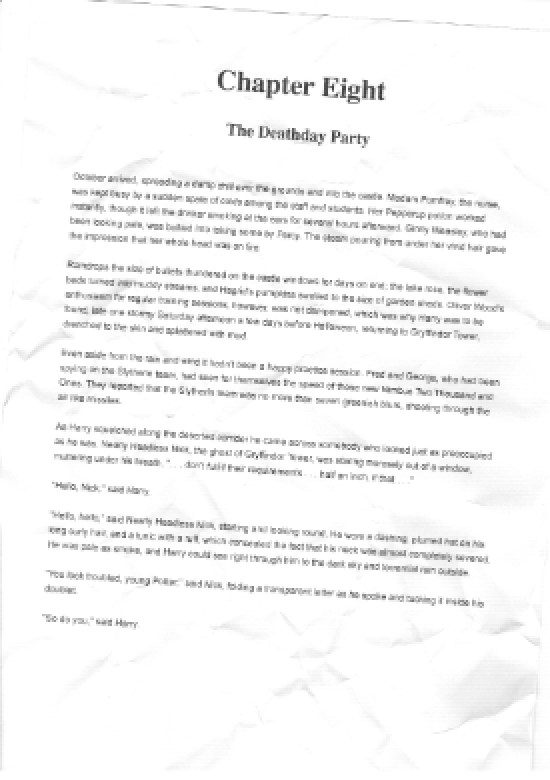
IronOCRが画像フィルターを使用して正確に処理できるノイズのある低解像度の文書
歪みやデジタル ノイズを含む不完全なスキャンを処理する場合、 IronOCR は他の C# OCR ライブラリよりも優れたパフォーマンスを発揮します。 これは、純粋なテスト画像ではなく、現実世界のシナリオ向けに特別に設計されています。
using IronOcr;

IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.LowQuality.tiff", pageindices);
input.Deskew(); // removes rotation and perspective
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.LowQuality.tiff", pageindices);
input.Deskew(); // removes rotation and perspective
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.LowQuality.tiff", pageindices)
input.Deskew() ' removes rotation and perspective
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.LowQuality.tiff", pageindices)
input.Deskew() ' removes rotation and perspective
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)Input.Deskew()を使用することで、低品質のスキャンでも正確さが著しく向上し、高品質の結果にほぼ一致します。 これは、Tesseract の複雑さがなく、C# OCR に IronOCR が最適な選択肢である理由を示しています。
画像フィルターにより処理時間がわずかに長くなる可能性がありますが、全体的な OCR の所要時間が大幅に短縮されます。 適切なバランスを見つけるには、ドキュメントの品質が重要になります。
ほとんどのシナリオにおいて、Input.Deskew() と Input.DeNoise() はOCRパフォーマンスに信頼性のある改善を提供します。 画像の前処理技術について詳しく知る。
OCR のパフォーマンスと速度を最適化するにはどうすればよいでしょうか?
C# で画像をテキストに変換するときに OCR 速度に影響を与える最も重要な要素は、入力品質です。 ノイズが最小限で DPI がより高い (約 200 dpi) 場合、最も高速かつ正確な結果が得られます。
IronOCR は不完全な文書の修正に優れていますが、この機能強化には追加の処理時間が必要になります。
圧縮アーティファクトが最小限の画像形式を選択します。 TIFF と PNG は通常、デジタル ノイズが少ないため、JPEG よりも結果が速くなります。
どの画像フィルターが OCR 速度を向上させるのでしょうか?
次のフィルターを使用すると、C# OCR 画像からテキストへのワークフローのパフォーマンスを大幅に向上できます。
OcrInput.Rotate(double degrees): 画像を時計回りに回転します(反時計回りの場合は負の値)OcrInput.Binarize(): 白黒に変換し、低コントラストのシナリオでのパフォーマンスを向上OcrInput.ToGrayScale(): グレースケールに変換し、速度の改善の可能性を持つOcrInput.Contrast(): より良い正確さのためにコントラストを自動調整OcrInput.DeNoise(): ノイズが予期される場合にデジタルアーティファクトを削除OcrInput.Invert(): 白黒のテキストのために色を反転OcrInput.Dilate(): テキストの境界を拡張OcrInput.Erode(): テキストの境界を縮小OcrInput.Deskew(): 整列を矯正 - 傾いたドキュメントに必須OcrInput.Despeckle(): 攻撃的なノイズ除去OcrInput.EnhanceResolution: 低解像度画像の品質を向上OcrInput.DetectPageOrientation(): ページの回転を検出し、修正します。 精度/速度のトレードオフを制御するためにOrientationDetectionModeを渡します:Fast,Balanced,Detailed, またはExtremeDetailed(v2025.8.6追加)
Scale() と EnhanceResolution() は、v2025.12.3 の既知の問題により SaveAsSearchablePdf() と互換性がありません。他のすべてのフィルターは、検索可能なPDF出力と正しく動作します。IronOCR を最高速度で設定するにはどうすればいいですか?
高品質のスキャンを処理する際の速度を最適化するには、次の設定を使用します。
using IronOcr;

IronTesseract ocr = new IronTesseract();

// Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\\";
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto;
ocr.Language = OcrLanguage.EnglishFast;

using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);

OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
IronTesseract ocr = new IronTesseract();
// Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\\";
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto;
ocr.Language = OcrLanguage.EnglishFast;
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Private ocr As New IronTesseract()
' Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\"
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto
ocr.Language = OcrLanguage.EnglishFast
Using input As New OcrInput()
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End UsingImports IronOcr
Private ocr As New IronTesseract()
' Configure for speed
ocr.Configuration.BlackListCharacters = "~`$#^*_}{][|\"
ocr.Configuration.PageSegmentationMode = TesseractPageSegmentationMode.Auto
ocr.Language = OcrLanguage.EnglishFast
Using input As New OcrInput()
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("img\Potter.tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End Usingこの最適化された設定は、デフォルトの設定と比較して、処理速度を改善しつつ高い精度を維持します。
C# OCRを使用して画像の特定の領域を読み取る方法は?
以下のIron Tesseract C#の例では、System.Drawing.Rectangleを使用して特定の領域をターゲットにする方法を示しています。 この手法は、テキストが予測可能な場所に表示される標準化されたフォームを処理する場合に非常に役立ちます。
IronOCR は切り取られた領域を処理してより速く結果を得ることができますか?
ピクセルベースの座標を使用すると、OCR を特定の領域に制限できるため、速度が大幅に向上し、不要なテキストの抽出を防ぐことができます。
using IronOcr;
using IronSoftware.Drawing;

IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
// restrict OCR to a content area for faster processing
Rectangle contentArea = new Rectangle(x: 215, y: 1250, height: 280, width: 1335);
input.LoadImage("img/ComSci.png", contentArea);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
using IronOcr;
using IronSoftware.Drawing;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
// restrict OCR to a content area for faster processing
Rectangle contentArea = new Rectangle(x: 215, y: 1250, height: 280, width: 1335);
input.LoadImage("img/ComSci.png", contentArea);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);Imports IronOcr
Imports IronSoftware.Drawing
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' restrict OCR to a content area for faster processing
Dim contentArea As New Rectangle(x:=215, y:=1250, height:=280, width:=1335)
input.LoadImage("img/ComSci.png", contentArea)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End UsingImports IronOcr
Imports IronSoftware.Drawing
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' restrict OCR to a content area for faster processing
Dim contentArea As New Rectangle(x:=215, y:=1250, height:=280, width:=1335)
input.LoadImage("img/ComSci.png", contentArea)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
End Usingこのターゲットを絞ったアプローチにより、関連するテキストのみを抽出しながら、速度が 41% 向上します。 請求書、小切手、フォームなどの構造化された文書に最適です。 同じ切り取り手法は、PDF OCR 操作でもシームレスに機能します。
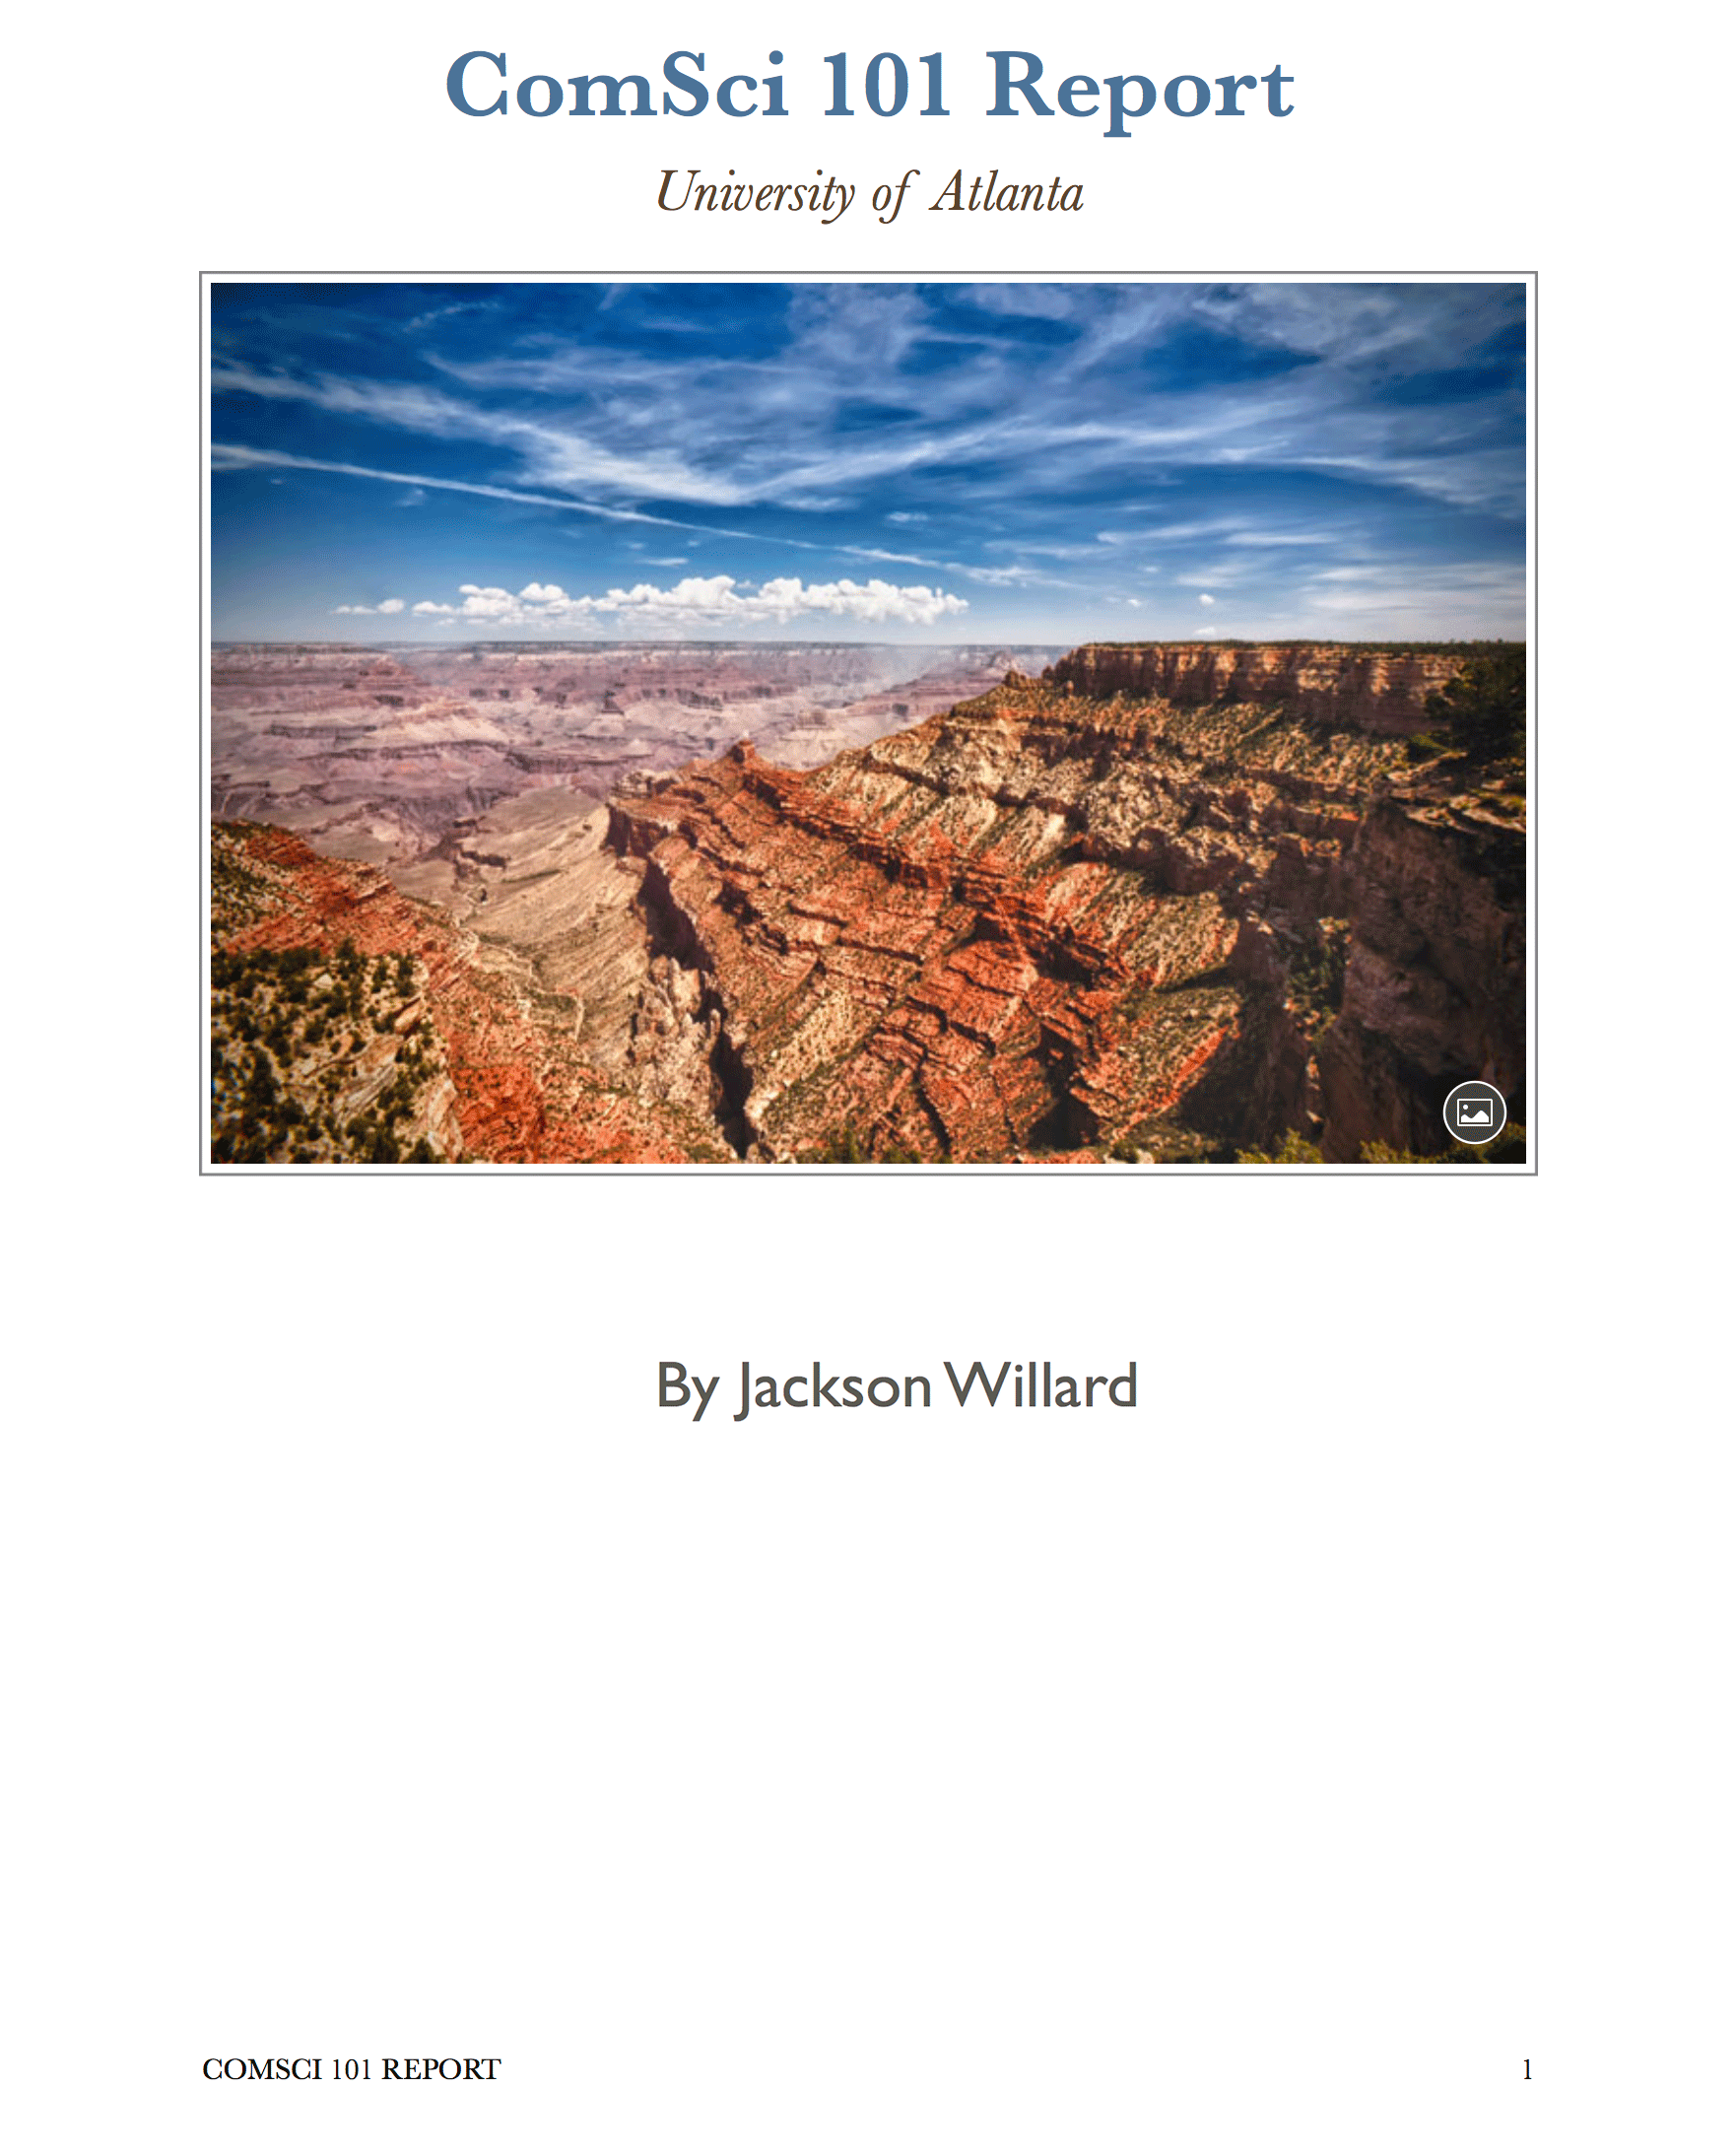 IronOCRの長方形選択を使用した正確な領域ベースのテキスト抽出を示すドキュメント
IronOCR はいくつの言語をサポートしていますか?
IronOCRは、便利な言語パックを通じて127の国際言語に対応しています。 DLLとして当社のウェブサイトから、またはNuGetパッケージマネージャー経由でダウンロードしてください。
言語パックは、NuGetインターフェース(「IronOcr.Languages」を検索)を介してインストールするか、完全な言語パックリストを訪問してください。
サポートされている言語には、アラビア語、中国語(簡体字/繁体字)、日本語、韓国語、ヒンディー語、ロシア語、ドイツ語、フランス語、スペイン語など 115 以上の言語があり、それぞれ正確なテキスト認識が最適化されています。
複数の言語で OCR を実装するにはどうすればよいでしょうか?
この IronOCR C# チュートリアルの例では、アラビア語のテキスト認識を示します。
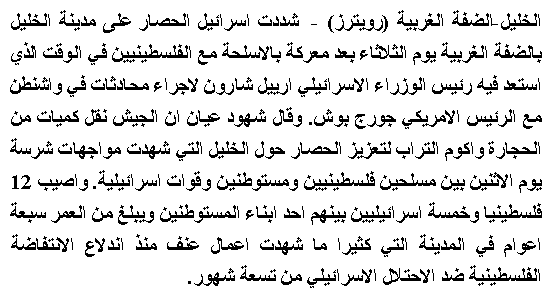
IronOCRはGIF画像からアラビア語のテキストを正確に抽出します
// PM> Install IronOcr.Languages.Arabic
using IronOcr;

IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.Arabic;

using OcrInput input = new OcrInput();
input.LoadImageFrame("img/arabic.gif", 1);
// add image filters if needed
// In this case, even thought input is very low quality
// IronTesseract can read what conventional Tesseract cannot.

OcrResult result = ocr.Read(input);

// Console can't print Arabic on Windows easily.
// Let's save to disk instead.
result.SaveAsTextFile("arabic.txt");
// PM> Install IronOcr.Languages.Arabic
using IronOcr;
IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.Arabic;
using OcrInput input = new OcrInput();
input.LoadImageFrame("img/arabic.gif", 1);
// add image filters if needed
// In this case, even thought input is very low quality
// IronTesseract can read what conventional Tesseract cannot.
OcrResult result = ocr.Read(input);
// Console can't print Arabic on Windows easily.
// Let's save to disk instead.
result.SaveAsTextFile("arabic.txt");' PM> Install IronOcr.Languages.Arabic
Imports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.Arabic
Using input As New OcrInput()
input.LoadImageFrame("img/arabic.gif", 1)
' add image filters if needed
' In this case, even thought input is very low quality
' IronTesseract can read what conventional Tesseract cannot.
Dim result As OcrResult = ocr.Read(input)
' Console can't print Arabic on Windows easily.
' Let's save to disk instead.
result.SaveAsTextFile("arabic.txt")
End Using' PM> Install IronOcr.Languages.Arabic
Imports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.Arabic
Using input As New OcrInput()
input.LoadImageFrame("img/arabic.gif", 1)
' add image filters if needed
' In this case, even thought input is very low quality
' IronTesseract can read what conventional Tesseract cannot.
Dim result As OcrResult = ocr.Read(input)
' Console can't print Arabic on Windows easily.
' Let's save to disk instead.
result.SaveAsTextFile("arabic.txt")
End UsingIronOCR は複数言語の文書を処理できますか?
ドキュメントに混合言語が含まれている場合は、IronOCR を多言語サポート用に設定します。
using IronOcr;

IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.ChineseSimplified;

// We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English);
// Optionally add custom tesseract .traineddata files by specifying a file path

using OcrInput input = new OcrInput();
input.LoadImage("img/MultiLanguage.jpeg");
OcrResult result = ocr.Read(input);
result.SaveAsTextFile("MultiLanguage.txt");
using IronOcr;
IronTesseract ocr = new IronTesseract();
ocr.Language = OcrLanguage.ChineseSimplified;
// We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English);
// Optionally add custom tesseract .traineddata files by specifying a file path
using OcrInput input = new OcrInput();
input.LoadImage("img/MultiLanguage.jpeg");
OcrResult result = ocr.Read(input);
result.SaveAsTextFile("MultiLanguage.txt");Imports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.ChineseSimplified
' We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English)
' Optionally add custom tesseract .traineddata files by specifying a file path
Using input As New OcrInput()
input.LoadImage("img/MultiLanguage.jpeg")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsTextFile("MultiLanguage.txt")
End UsingImports IronOcr
Private ocr As New IronTesseract()
ocr.Language = OcrLanguage.ChineseSimplified
' We can add any number of languages.
ocr.AddSecondaryLanguage(OcrLanguage.English)
' Optionally add custom tesseract .traineddata files by specifying a file path
Using input As New OcrInput()
input.LoadImage("img/MultiLanguage.jpeg")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsTextFile("MultiLanguage.txt")
End UsingマルチページドキュメントをC# OCRで処理する方法は?
IronOCRは、複数ページまたは画像を単一のOcrResultに結合します。 この機能により、検索可能なPDFの作成やドキュメントセット全体からテキストを抽出する能力が強化されます。
1 回の OCR 操作で、画像、TIFF フレーム、PDF ページなど、さまざまなソースを組み合わせて使用できます。
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);

OcrResult result = ocr.Read(input);

Console.WriteLine($"{result.Pages.Length} Pages"); // 3 Pages
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine($"{result.Pages.Length} Pages"); // 3 PagesImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine($"{result.Pages.Length} Pages") ' 3 PagesImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine($"{result.Pages.Length} Pages") ' 3 PagesTIFF ファイルのすべてのページを効率的に処理します。
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("MultiFrame.Tiff", pageindices);
OcrResult result = ocr.Read(input);

Console.WriteLine(result.Text);
Console.WriteLine($"{result.Pages.Length} Pages");
// 1 page for every frame (page) in the TIFF
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("MultiFrame.Tiff", pageindices);
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
Console.WriteLine($"{result.Pages.Length} Pages");
// 1 page for every frame (page) in the TIFFImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("MultiFrame.Tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
Console.WriteLine($"{result.Pages.Length} Pages")
' 1 page for every frame (page) in the TIFFImports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
Private pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("MultiFrame.Tiff", pageindices)
Dim result As OcrResult = ocr.Read(input)
Console.WriteLine(result.Text)
Console.WriteLine($"{result.Pages.Length} Pages")
' 1 page for every frame (page) in the TIFFTIFF または PDF を検索可能な形式に変換します。
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
input.Title = "Quarterly Report";
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);

OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
input.Title = "Quarterly Report";
input.LoadImage("image1.jpeg");
input.LoadImage("image2.png");
var pageindices = new int[] { 1, 2 };
input.LoadImageFrames("image3.gif", pageindices);
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Quarterly Report"
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Quarterly Report"
input.LoadImage("image1.jpeg")
input.LoadImage("image2.png")
Dim pageindices = New Integer() { 1, 2 }
input.LoadImageFrames("image3.gif", pageindices)
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")既存の PDF を検索可能なバージョンに変換します。
using IronOcr;

IronTesseract ocr = new IronTesseract();

using OcrInput input = new OcrInput();
input.Title = "Pdf Metadata Name";
input.LoadPdf("example.pdf", Password: "password");
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");
using IronOcr;
IronTesseract ocr = new IronTesseract();
using OcrInput input = new OcrInput();
input.Title = "Pdf Metadata Name";
input.LoadPdf("example.pdf", Password: "password");
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Pdf Metadata Name"
input.LoadPdf("example.pdf", Password:= "password")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")Imports IronOcr
Private ocr As New IronTesseract()
Private OcrInput As using
input.Title = "Pdf Metadata Name"
input.LoadPdf("example.pdf", Password:= "password")
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")同じ手法を TIFF 変換に適用します。
using IronOcr;

var ocr = new IronTesseract();

using (var input = new OcrInput())
{
    // Configure document properties
    input.Title = "Scanned Archive Document";

    // Select pages to process
    var pageIndices = new int[] { 1, 2 };
    input.LoadImageFrames("example.tiff", pageIndices);

    // Create searchable PDF from TIFF
    OcrResult result = ocr.Read(input);
    result.SaveAsSearchablePdf("searchable.pdf");
}
using IronOcr;
var ocr = new IronTesseract();
using (var input = new OcrInput())
{
// Configure document properties
input.Title = "Scanned Archive Document";
// Select pages to process
var pageIndices = new int[] { 1, 2 };
input.LoadImageFrames("example.tiff", pageIndices);
// Create searchable PDF from TIFF
OcrResult result = ocr.Read(input);
result.SaveAsSearchablePdf("searchable.pdf");
}Imports IronOcr
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' Configure document properties
input.Title = "Scanned Archive Document"
' Select pages to process
Dim pageIndices As Integer() = {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Create searchable PDF from TIFF
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")
End UsingImports IronOcr
Dim ocr As New IronTesseract()
Using input As New OcrInput()
' Configure document properties
input.Title = "Scanned Archive Document"
' Select pages to process
Dim pageIndices As Integer() = {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Create searchable PDF from TIFF
Dim result As OcrResult = ocr.Read(input)
result.SaveAsSearchablePdf("searchable.pdf")
End UsingOCR の結果を HOCR HTML としてエクスポートするにはどうすればいいですか?
IronOCR は HOCR HTML エクスポートをサポートしており、レイアウト情報を保持しながら構造化されたPDF から HTMLおよびTIFF から HTML への変換を可能にします。
using IronOcr;

var ocr = new IronTesseract();

using (var input = new OcrInput())
{
    // Set HTML title
    input.Title = "Document Archive";

    // Process multiple document types
    input.LoadImage("image2.jpeg");
    input.LoadPdf("example.pdf", Password: "password");

    // Add TIFF pages
    var pageIndices = new int[] { 1, 2 };
    input.LoadImageFrames("example.tiff", pageIndices);

    // Export as HOCR with position data
    OcrResult result = ocr.Read(input);
    result.SaveAsHocrFile("hocr.html");
}
using IronOcr;
var ocr = new IronTesseract();
using (var input = new OcrInput())
{
// Set HTML title
input.Title = "Document Archive";
// Process multiple document types
input.LoadImage("image2.jpeg");
input.LoadPdf("example.pdf", Password: "password");
// Add TIFF pages
var pageIndices = new int[] { 1, 2 };
input.LoadImageFrames("example.tiff", pageIndices);
// Export as HOCR with position data
OcrResult result = ocr.Read(input);
result.SaveAsHocrFile("hocr.html");
}Imports IronOcr
Dim ocr = New IronTesseract()
Using input = New OcrInput()
' Set HTML title
input.Title = "Document Archive"
' Process multiple document types
input.LoadImage("image2.jpeg")
input.LoadPdf("example.pdf", Password:="password")
' Add TIFF pages
Dim pageIndices = New Integer() {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Export as HOCR with position data
Dim result As OcrResult = ocr.Read(input)
result.SaveAsHocrFile("hocr.html")
End UsingImports IronOcr
Dim ocr = New IronTesseract()
Using input = New OcrInput()
' Set HTML title
input.Title = "Document Archive"
' Process multiple document types
input.LoadImage("image2.jpeg")
input.LoadPdf("example.pdf", Password:="password")
' Add TIFF pages
Dim pageIndices = New Integer() {1, 2}
input.LoadImageFrames("example.tiff", pageIndices)
' Export as HOCR with position data
Dim result As OcrResult = ocr.Read(input)
result.SaveAsHocrFile("hocr.html")
End UsingIronOCR はテキストと一緒にバーコードも読み取ることができますか?
IronOCRは、バーコード読み取り機能とテキスト認識を独自に組み合わせて、別々のライブラリの必要性を排除します。
// Enable combined text and barcode recognition
using IronOcr;

var ocr = new IronTesseract();

// Enable barcode detection
ocr.Configuration.ReadBarCodes = true;

using (var input = new OcrInput())
{
    // Load image containing both text and barcodes
    input.LoadImage("img/Barcode.png");

    // Process both text and barcodes
    var result = ocr.Read(input);

    // Extract barcode data
    foreach (var barcode in result.Barcodes)
    {
        Console.WriteLine($"Barcode Value: {barcode.Value}");
        Console.WriteLine($"Format: {barcode.Format}");
    }
}
// Enable combined text and barcode recognition
using IronOcr;
var ocr = new IronTesseract();
// Enable barcode detection
ocr.Configuration.ReadBarCodes = true;
using (var input = new OcrInput())
{
// Load image containing both text and barcodes
input.LoadImage("img/Barcode.png");
// Process both text and barcodes
var result = ocr.Read(input);
// Extract barcode data
foreach (var barcode in result.Barcodes)
{
Console.WriteLine($"Barcode Value: {barcode.Value}");
Console.WriteLine($"Format: {barcode.Format}");
}
}' Enable combined text and barcode recognition
Imports IronOcr
Dim ocr = New IronTesseract()
' Enable barcode detection
ocr.Configuration.ReadBarCodes = True
Using input = New OcrInput()
' Load image containing both text and barcodes
input.LoadImage("img/Barcode.png")
' Process both text and barcodes
Dim result = ocr.Read(input)
' Extract barcode data
For Each barcode In result.Barcodes
Console.WriteLine($"Barcode Value: {barcode.Value}")
Console.WriteLine($"Format: {barcode.Format}")
Next
End Using' Enable combined text and barcode recognition
Imports IronOcr
Dim ocr = New IronTesseract()
' Enable barcode detection
ocr.Configuration.ReadBarCodes = True
Using input = New OcrInput()
' Load image containing both text and barcodes
input.LoadImage("img/Barcode.png")
' Process both text and barcodes
Dim result = ocr.Read(input)
' Extract barcode data
For Each barcode In result.Barcodes
Console.WriteLine($"Barcode Value: {barcode.Value}")
Console.WriteLine($"Format: {barcode.Format}")
Next
End Using詳細な OCR 結果とメタデータにアクセスするにはどうすればよいでしょうか?
IronOCR 結果オブジェクトは、上級開発者が高度なアプリケーションに活用できる包括的なデータを提供します。
各OcrResultには、ページ、段落、行、単語、文字の階層のコレクションが含まれています。 すべての要素には、場所、フォント情報、信頼スコアなどの詳細なメタデータが含まれます。
個々の要素 (段落、単語、バーコード) は、画像またはビットマップとしてエクスポートして、さらに処理することができます。
using System;
using IronOcr;
using IronSoftware.Drawing;

// Configure with barcode support
IronTesseract ocr = new IronTesseract
{
    Configuration = { ReadBarCodes = true }
};

using OcrInput input = new OcrInput();

// Process multi-page document
int[] pageIndices = { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageIndices);

OcrResult result = ocr.Read(input);

// Navigate the complete results hierarchy
foreach (var page in result.Pages)
{
    // Page-level data
    int pageNumber = page.PageNumber;
    string pageText = page.Text;
    int pageWordCount = page.WordCount;

    // Extract page elements
    OcrResult.Barcode[] barcodes = page.Barcodes;
    AnyBitmap pageImage = page.ToBitmap(input);
    double pageWidth = page.Width;
    double pageHeight = page.Height;

    foreach (var paragraph in page.Paragraphs)
    {
        // Paragraph properties
        int paragraphNumber = paragraph.ParagraphNumber;
        string paragraphText = paragraph.Text;
        double paragraphConfidence = paragraph.Confidence;
        var textDirection = paragraph.TextDirection;

        foreach (var line in paragraph.Lines)
        {
            // Line details including baseline information
            string lineText = line.Text;
            double lineConfidence = line.Confidence;
            double baselineAngle = line.BaselineAngle;
            double baselineOffset = line.BaselineOffset;

            foreach (var word in line.Words)
            {
                // Word-level data
                string wordText = word.Text;
                double wordConfidence = word.Confidence;

                // Font information (when available)
                if (word.Font != null)
                {
                    string fontName = word.Font.FontName;
                    double fontSize = word.Font.FontSize;
                    bool isBold = word.Font.IsBold;
                    bool isItalic = word.Font.IsItalic;
                }

                foreach (var character in word.Characters)
                {
                    // Character-level analysis
                    string charText = character.Text;
                    double charConfidence = character.Confidence;

                    // Alternative character choices for spell-checking
                    OcrResult.Choice[] alternatives = character.Choices;
                }
            }
        }
    }
}
using System;
using IronOcr;
using IronSoftware.Drawing;
// Configure with barcode support
IronTesseract ocr = new IronTesseract
{
Configuration = { ReadBarCodes = true }
};
using OcrInput input = new OcrInput();
// Process multi-page document
int[] pageIndices = { 1, 2 };
input.LoadImageFrames(@"img\Potter.tiff", pageIndices);
OcrResult result = ocr.Read(input);
// Navigate the complete results hierarchy
foreach (var page in result.Pages)
{
// Page-level data
int pageNumber = page.PageNumber;
string pageText = page.Text;
int pageWordCount = page.WordCount;
// Extract page elements
OcrResult.Barcode[] barcodes = page.Barcodes;
AnyBitmap pageImage = page.ToBitmap(input);
double pageWidth = page.Width;
double pageHeight = page.Height;
foreach (var paragraph in page.Paragraphs)
{
// Paragraph properties
int paragraphNumber = paragraph.ParagraphNumber;
string paragraphText = paragraph.Text;
double paragraphConfidence = paragraph.Confidence;
var textDirection = paragraph.TextDirection;
foreach (var line in paragraph.Lines)
{
// Line details including baseline information
string lineText = line.Text;
double lineConfidence = line.Confidence;
double baselineAngle = line.BaselineAngle;
double baselineOffset = line.BaselineOffset;
foreach (var word in line.Words)
{
// Word-level data
string wordText = word.Text;
double wordConfidence = word.Confidence;
// Font information (when available)
if (word.Font != null)
{
string fontName = word.Font.FontName;
double fontSize = word.Font.FontSize;
bool isBold = word.Font.IsBold;
bool isItalic = word.Font.IsItalic;
}
foreach (var character in word.Characters)
{
// Character-level analysis
string charText = character.Text;
double charConfidence = character.Confidence;
// Alternative character choices for spell-checking
OcrResult.Choice[] alternatives = character.Choices;
}
}
}
}
}Imports System
Imports IronOcr
Imports IronSoftware.Drawing
' Configure with barcode support
Dim ocr As New IronTesseract With {
.Configuration = New OcrConfiguration With {
.ReadBarCodes = True
}
}
Using input As New OcrInput()
' Process multi-page document
Dim pageIndices() As Integer = {1, 2}
input.LoadImageFrames("img\Potter.tiff", pageIndices)
Dim result As OcrResult = ocr.Read(input)
' Navigate the complete results hierarchy
For Each page In result.Pages
' Page-level data
Dim pageNumber As Integer = page.PageNumber
Dim pageText As String = page.Text
Dim pageWordCount As Integer = page.WordCount
' Extract page elements
Dim barcodes() As OcrResult.Barcode = page.Barcodes
Dim pageImage As AnyBitmap = page.ToBitmap(input)
Dim pageWidth As Double = page.Width
Dim pageHeight As Double = page.Height
For Each paragraph In page.Paragraphs
' Paragraph properties
Dim paragraphNumber As Integer = paragraph.ParagraphNumber
Dim paragraphText As String = paragraph.Text
Dim paragraphConfidence As Double = paragraph.Confidence
Dim textDirection = paragraph.TextDirection
For Each line In paragraph.Lines
' Line details including baseline information
Dim lineText As String = line.Text
Dim lineConfidence As Double = line.Confidence
Dim baselineAngle As Double = line.BaselineAngle
Dim baselineOffset As Double = line.BaselineOffset
For Each word In line.Words
' Word-level data
Dim wordText As String = word.Text
Dim wordConfidence As Double = word.Confidence
' Font information (when available)
If word.Font IsNot Nothing Then
Dim fontName As String = word.Font.FontName
Dim fontSize As Double = word.Font.FontSize
Dim isBold As Boolean = word.Font.IsBold
Dim isItalic As Boolean = word.Font.IsItalic
End If
For Each character In word.Characters
' Character-level analysis
Dim charText As String = character.Text
Dim charConfidence As Double = character.Confidence
' Alternative character choices for spell-checking
Dim alternatives() As OcrResult.Choice = character.Choices
Next
Next
Next
Next
Next
End UsingImports System
Imports IronOcr
Imports IronSoftware.Drawing
' Configure with barcode support
Dim ocr As New IronTesseract With {
.Configuration = New OcrConfiguration With {
.ReadBarCodes = True
}
}
Using input As New OcrInput()
' Process multi-page document
Dim pageIndices() As Integer = {1, 2}
input.LoadImageFrames("img\Potter.tiff", pageIndices)
Dim result As OcrResult = ocr.Read(input)
' Navigate the complete results hierarchy
For Each page In result.Pages
' Page-level data
Dim pageNumber As Integer = page.PageNumber
Dim pageText As String = page.Text
Dim pageWordCount As Integer = page.WordCount
' Extract page elements
Dim barcodes() As OcrResult.Barcode = page.Barcodes
Dim pageImage As AnyBitmap = page.ToBitmap(input)
Dim pageWidth As Double = page.Width
Dim pageHeight As Double = page.Height
For Each paragraph In page.Paragraphs
' Paragraph properties
Dim paragraphNumber As Integer = paragraph.ParagraphNumber
Dim paragraphText As String = paragraph.Text
Dim paragraphConfidence As Double = paragraph.Confidence
Dim textDirection = paragraph.TextDirection
For Each line In paragraph.Lines
' Line details including baseline information
Dim lineText As String = line.Text
Dim lineConfidence As Double = line.Confidence
Dim baselineAngle As Double = line.BaselineAngle
Dim baselineOffset As Double = line.BaselineOffset
For Each word In line.Words
' Word-level data
Dim wordText As String = word.Text
Dim wordConfidence As Double = word.Confidence
' Font information (when available)
If word.Font IsNot Nothing Then
Dim fontName As String = word.Font.FontName
Dim fontSize As Double = word.Font.FontSize
Dim isBold As Boolean = word.Font.IsBold
Dim isItalic As Boolean = word.Font.IsItalic
End If
For Each character In word.Characters
' Character-level analysis
Dim charText As String = character.Text
Dim charConfidence As Double = character.Confidence
' Alternative character choices for spell-checking
Dim alternatives() As OcrResult.Choice = character.Choices
Next
Next
Next
Next
Next
End Usingまとめ
IronOCRは、Windows、Linux、Macプラットフォーム全体で動作する最も先進的なTesseract API実装をC#開発者に提供します。 IronOCR を使用して、不完全なドキュメントからでも画像からテキストを正確に読み取ることができる機能は、基本的な OCR ソリューションとは一線を画しています。
ライブラリの独自の機能には、統合バーコード読み取り機能や、結果を検索可能な PDF または HOCR HTML としてエクスポートする機能などがあり、これらの機能は標準の Tesseract 実装では利用できません。
前進
IronOCR の習得を続けるには:
- 当社の包括的なスタートガイドを探索
- 実用的なC#コードの例を閲覧
- 詳細なAPIドキュメントを参考に
ソースコードのダウンロード
アプリケーションに C# OCR 画像からテキストへの変換を実装する準備はできていますか? IronOCRをダウンロードして、今日から無料トライアルを始めましょう。
よくある質問
IronOCRとは何ですか、そしてTesseractとどのように違いますか?
IronOCRはC#のOCRライブラリで、複雑なインストールや設定なしに画像をテキストに変換します。Tesseractエンジンを取り入れつつ、.NETアプリケーション向けに最適化しています。
C# IronOCRを使って画像からテキストを抽出するにはどうすればいいですか?
IronOCRを使用して画像からテキストを抽出するには、IronTesseractクラスを使用します。簡単な利用の場合、新しいインスタンスを初期化し、画像ファイルパスと共にReadメソッドを呼び出すことで、認識されたテキストを取得します。
IronOCRはどの画像ファイル形式をサポートしていますか?
IronOCRは、JPEG、TIFF、GIF、BMP、PNGを含むさまざまな画像形式をサポートしています。また、PDF全体または特定のページを処理することもできます。
画像フィルターはIronOCRのOCR精度をどのように向上させますか?
IronOCRの画像フィルターは、画像の歪み、ノイズ、コントラストの悪さなどを修正することでOCRの精度を向上させます。Deskew、DeNoise、EnhanceResolutionのようなフィルターがよく使われ、入力品質を改善します。
IronOCRは複数の言語に対応できますか?
はい、IronOCRは127の国際言語をサポートしています。NuGetまたはIron Softwareのウェブサイトから言語パックをダウンロードし、簡単に異なる言語でのテキスト認識を設定できます。
IronOCRは特定の領域でのテキスト抽出にどのように使用できますか?
IronOCRはSystem.Drawing.Rectangleを使用して特定領域をターゲットにしてテキストを抽出でき、OCR操作を定義された領域に限定し、速度を向上させ不要なテキスト抽出を防ぎます。
マルチページ文書処理のためにIronOCRを使用する利点は何ですか?
IronOCRは単一のOCR操作で複数のページや画像を処理でき、検索可能なPDFに統合したり、完全なテキスト文書として抽出したりすることができます。
IronOCRはOCR結果のHTMLエクスポートをサポートしていますか?
はい、IronOCRはHOCR HTMLとしてOCR結果をエクスポートでき、レイアウト情報を保持し、PDFやTIFFの構造化されたHTMLへの変換を可能にします。
IronOCRはテキストと共にバーコードを読めますか?
IronOCRはテキスト認識に加えてバーコードを読み取ることができ、両方の機能を単一のライブラリで提供し、別のバーコード読み取りソフトウェアが不要になります。
IronOCRをより迅速なOCR処理のために最適化するにはどうすればいいですか?
IronOCRをスピードのために最適化するには、ノイズの少ない高品質な画像を使用し、適切な画像フィルターを利用し、BlackListCharactersやPageSegmentationModeの設定を最適化するなどがあります。

Jacob Mellorは、Iron Softwareの最高技術責任者であり、C# PDF技術を先導するビジョナリーなエンジニアです。Iron Softwareのコアコードベースの最初の開発者として、CEOのCameron Rimingtonと共に、NASA、Tesla、および世界中の政府機関を対象にサービスを提供する50人以上の企業に変革しました。

